adds support for "thinking tokens" - a feature that exposes the model's reasoning process before providing the final response. Key improvements include:

- Add a new Thinking class to handle thinking content from LLMs
- Modify endpoints (Claude, AWS Bedrock) to handle thinking output
- Update AI bot to display thinking in collapsible details section
- Fix SEARCH/REPLACE blocks to support empty replacement strings and general improvements to artifact editing
- Allow configurable temperature in triage and report automations
- Various bug fixes and improvements to diff parsing
## 🔍 Overview
This update ensures that the streaming for discoveries is smoother, especially on first update.


## ➕ More details
To help with smoother streaming, the discovery preview (which was being tracked as a separate property in the JS logic) will be removed and the entire discovery content will be shown/hidden via the existing CSS. The preview was already receiving the full update even though it was visually hidden, so removing the separate property shouldn't have any negative performance hit. Visually hiding it with CSS only will help simplify the component and also allow for smoother streaming. We will instead remove the buffered streaming approach and instead use typing timers similar to what we did for streaming summarization.

No related tests as streaming animations are difficult to test.
This update improves some of the UI around sentiment analysis reports:

1. Improve titles so it is above and truncated when long
2. Change doughnut to only show total count
3. Ensures sentiment posts have dates
4. Ensure expand post doesn't appear on short posts
* FEATURE: full support for Sonnet 3.7

- Adds support for Sonnet 3.7 with reasoning on bedrock and anthropic
- Fixes regression where provider params were not populated

Note. reasoning tokens are hardcoded to minimum of 100 maximum of 65536

* FIX: open ai non reasoning models need to use deprecate max_tokens
* FIX: legacy reasoning models not working, missing provider params

1. Legacy reasoning models (o1-preview / o1-mini) do not support developer or system messages, do not use them.
2. LLM editor form not showing all provider params due to missing remap

* add system test
* FEATURE: Experimental search results from an AI Persona.

When a user searches discourse, we'll send the query to an AI Persona to provide additional context and enrich the results. The feature depends on the user being a member of a group to which the persona has access.

* Update assets/stylesheets/common/ai-blinking-animation.scss

Co-authored-by: Keegan George <[email protected]>

---------

Co-authored-by: Keegan George <[email protected]>
## 🔍 Overview
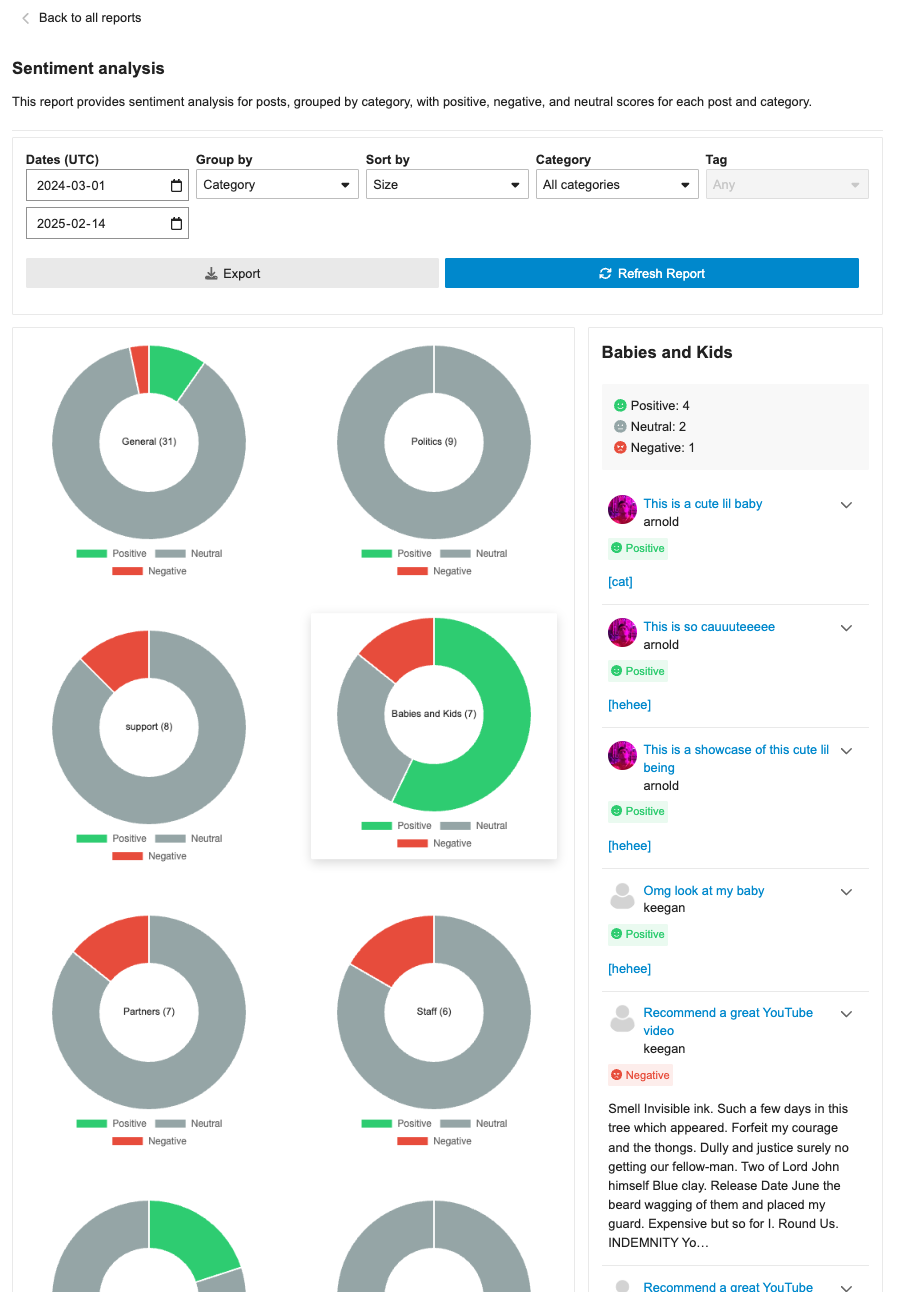
This update adds a new report page at `admin/reports/sentiment_analysis` where admins can see a sentiment analysis report for the forum grouped by either category or tags.
## ➕ More details
The report can breakdown either category or tags into positive/negative/neutral sentiments based on the grouping (category/tag). Clicking on the doughnut visualization will bring up a post list of all the posts that were involved in that classification with further sentiment classifications by post.
The report can additionally be sorted in alphabetical order or by size, as well as be filtered by either category/tag based on the grouping.
## 👨🏽💻 Technical Details
The new admin report is registered via the pluginAPi with `api.registerReportModeComponent` to register the custom sentiment doughnut report. However, when each doughnut visualization is clicked, a new endpoint found at: `/discourse-ai/sentiment/posts` is fetched to showcase posts classified by sentiments based on the respective params.
## 📸 Screenshots
The require for `discourse/config/environment` should point to the local user's core Discourse environment instead of the hardcoded path for Sam's env.
From [pgvector/pgvector](https://github.com/pgvector/pgvector) README

> With approximate indexes, filtering is applied after the index is scanned. If a condition matches 10% of rows, with HNSW and the default hnsw.ef_search of 40, only 4 rows will match on average. For more rows, increase hnsw.ef_search.
>
> Starting with 0.8.0, you can enable [iterative index scans](https://github.com/pgvector/pgvector#iterative-index-scans), which will automatically scan more of the index when needed.


Since we are stuck on 0.7.0 we are going the first option for now.
- Add non-contiguous search/replace support using ... syntax
- Add judge support for evaluating LLM outputs with ratings
- Improve error handling and reporting in eval runner
- Add full section replacement support without search blocks
- Add fabricators and specs for artifact diffing
- Track failed searches to improve debugging
- Add JS syntax validation for artifact versions in eval system
- Update prompt documentation with clear guidelines

* improve eval output

* move error handling

* llm as a judge

* fix spec

* small note on evals
 Sam
 Martin Brennan
 Kris
 Rafael dos Santos Silva
 Keegan George
 Discourse Translator Bot
 Natalie Tay
 Jarek Radosz
 Roman Rizzi