* FIX: Improve MessageBus efficiency and correctly stop streaming

This commit enhances the message bus implementation for AI helper streaming by:

- Adding client_id targeting for message bus publications to ensure only the requesting client receives streaming updates
- Limiting MessageBus backlog size (2) and age (60 seconds) to prevent Redis bloat
- Replacing clearTimeout with Ember's cancel method for proper runloop management, we were leaking a stop
- Adding tests for client-specific message delivery

These changes improve memory usage and make streaming more reliable by ensuring messages are properly directed to the requesting client.

* composer suggestion needed a fix as well.

* backlog size of 2 is risky here cause same channel name is reused between clients
Examples simulate previous interactions with an LLM and come
right after the system prompt. This helps grounding the model and
producing better responses.
* DEV: Use structured responses for summaries

* Fix system specs

* Make response_format a first class citizen and update endpoints to support it

* Response format can be specified in the persona

* lint

* switch to jsonb and make column nullable

* Reify structured output chunks. Move JSON parsing to the depths of Completion

* Switch to JsonStreamingTracker for partial JSON parsing
AI bots come in 2 flavors

1. An LLM and LLM user, in this case we should decorate posts with persona name
2. A Persona user, in this case, in PMs we decorate with LLM name

(2) is a significant improvement, cause previously when creating a conversation
you could not tell which LLM you were talking to by simply looking at the post, you would
have to scroll to the top of the page.

* lint

* translation missing
This update adds metrics for estimated spending in AI usage. To make use of it, admins must add cost details to the LLM config page (input, output, and cached input costs per 1M tokens). After doing so, the metrics will appear in the AI usage dashboard as the AI plugin is used.
In this feature update, we add the UI for the ability to easily configure persona backed AI-features. The feature will still be hidden until structured responses are complete.
Add API methods to AI tools for reading and updating personas, enabling
more flexible AI workflows. This allows custom tools to:

- Fetch persona information through discourse.getPersona()
- Update personas with modified settings via discourse.updatePersona()
- Also update using persona.update()

These APIs enable new use cases like "trainable" moderation bots, where
users with appropriate permissions can set and refine moderation rules
through direct chat interactions, without needing admin panel access.

Also adds a special API scope which allows people to lean on API
for similar actions

Additionally adds a rather powerful hidden feature can allow custom tools
to inject content into the context unconditionally it can be used for memory and similar features
This feature update allows for continuing the conversation with Discobot Discoveries in an AI bot chat. After discoveries gives you a response to your search you can continue with the existing context.
This change moves all the personas code into its own module. We want to treat them as a building block features can built on top of, same as `Completions::Llm`.

The code to title a message was moved from `Bot` to `Playground`.
* FEATURE: Experimental search results from an AI Persona.

When a user searches discourse, we'll send the query to an AI Persona to provide additional context and enrich the results. The feature depends on the user being a member of a group to which the persona has access.

* Update assets/stylesheets/common/ai-blinking-animation.scss

Co-authored-by: Keegan George <[email protected]>

---------

Co-authored-by: Keegan George <[email protected]>
## 🔍 Overview
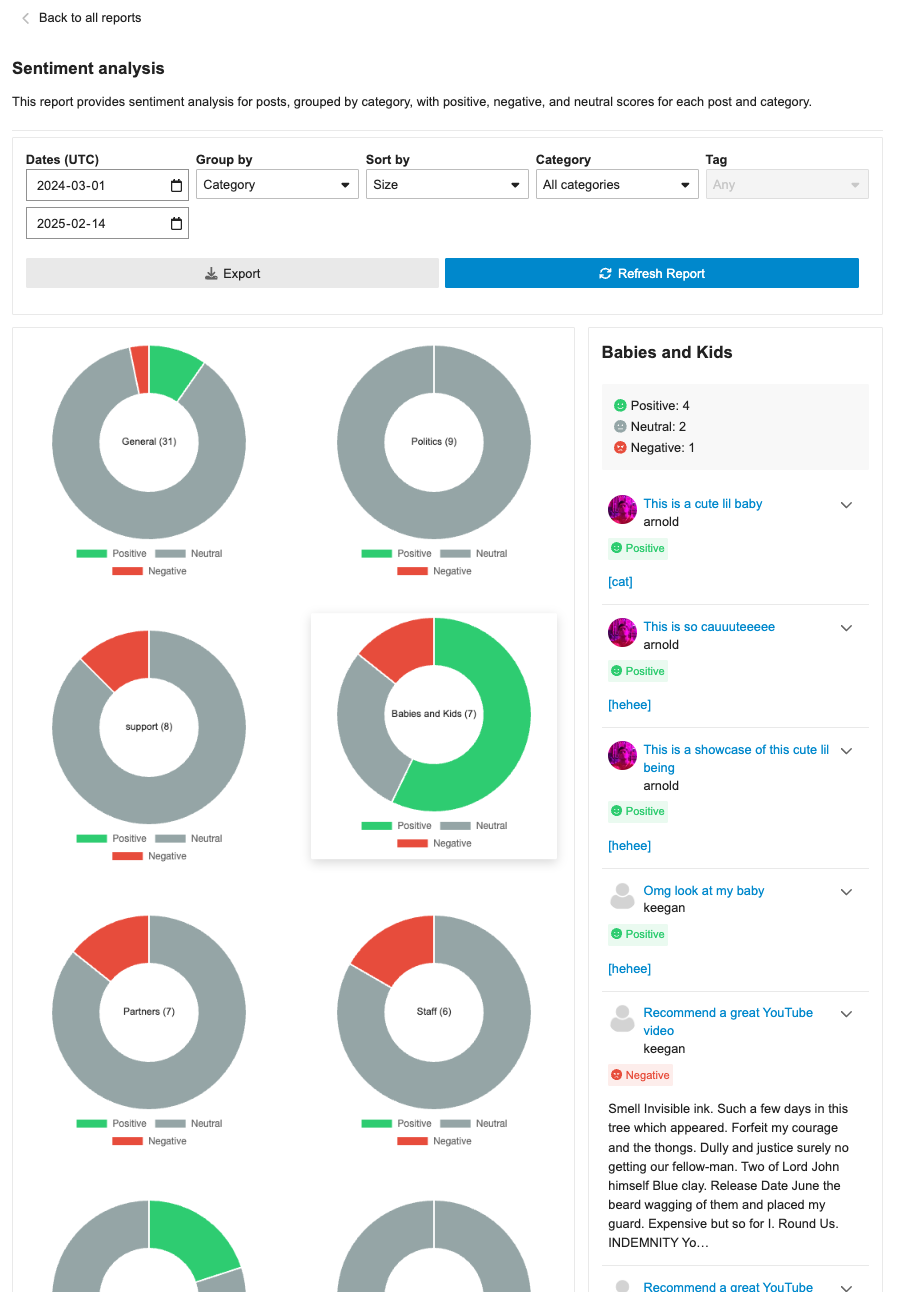
This update adds a new report page at `admin/reports/sentiment_analysis` where admins can see a sentiment analysis report for the forum grouped by either category or tags.
## ➕ More details
The report can breakdown either category or tags into positive/negative/neutral sentiments based on the grouping (category/tag). Clicking on the doughnut visualization will bring up a post list of all the posts that were involved in that classification with further sentiment classifications by post.
The report can additionally be sorted in alphabetical order or by size, as well as be filtered by either category/tag based on the grouping.
## 👨🏽💻 Technical Details
The new admin report is registered via the pluginAPi with `api.registerReportModeComponent` to register the custom sentiment doughnut report. However, when each doughnut visualization is clicked, a new endpoint found at: `/discourse-ai/sentiment/posts` is fetched to showcase posts classified by sentiments based on the respective params.
## 📸 Screenshots
* FEATURE: Native PDF support

This amends it so we use PDF Reader gem to extract text from PDFs

* This means that our simple pdf eval passes at last

* fix spec

* skip test in CI

* test file support

* Update lib/utils/image_to_text.rb

Co-authored-by: Alan Guo Xiang Tan <[email protected]>

* address pr comments

---------

Co-authored-by: Alan Guo Xiang Tan <[email protected]>
This PR introduces several enhancements and refactorings to the AI Persona and RAG (Retrieval-Augmented Generation) functionalities within the discourse-ai plugin. Here's a breakdown of the changes:

**1. LLM Model Association for RAG and Personas:**

-   **New Database Columns:** Adds `rag_llm_model_id` to both `ai_personas` and `ai_tools` tables. This allows specifying a dedicated LLM for RAG indexing, separate from the persona's primary LLM.  Adds `default_llm_id` and `question_consolidator_llm_id` to `ai_personas`.
-   **Migration:**  Includes a migration (`20250210032345_migrate_persona_to_llm_model_id.rb`) to populate the new `default_llm_id` and `question_consolidator_llm_id` columns in `ai_personas` based on the existing `default_llm` and `question_consolidator_llm` string columns, and a post migration to remove the latter.
-   **Model Changes:**  The `AiPersona` and `AiTool` models now `belong_to` an `LlmModel` via `rag_llm_model_id`. The `LlmModel.proxy` method now accepts an `LlmModel` instance instead of just an identifier.  `AiPersona` now has `default_llm_id` and `question_consolidator_llm_id` attributes.
-   **UI Updates:**  The AI Persona and AI Tool editors in the admin panel now allow selecting an LLM for RAG indexing (if PDF/image support is enabled).  The RAG options component displays an LLM selector.
-   **Serialization:** The serializers (`AiCustomToolSerializer`, `AiCustomToolListSerializer`, `LocalizedAiPersonaSerializer`) have been updated to include the new `rag_llm_model_id`, `default_llm_id` and `question_consolidator_llm_id` attributes.

**2. PDF and Image Support for RAG:**

-   **Site Setting:** Introduces a new hidden site setting, `ai_rag_pdf_images_enabled`, to control whether PDF and image files can be indexed for RAG. This defaults to `false`.
-   **File Upload Validation:** The `RagDocumentFragmentsController` now checks the `ai_rag_pdf_images_enabled` setting and allows PDF, PNG, JPG, and JPEG files if enabled.  Error handling is included for cases where PDF/image indexing is attempted with the setting disabled.
-   **PDF Processing:** Adds a new utility class, `DiscourseAi::Utils::PdfToImages`, which uses ImageMagick (`magick`) to convert PDF pages into individual PNG images. A maximum PDF size and conversion timeout are enforced.
-   **Image Processing:** A new utility class, `DiscourseAi::Utils::ImageToText`, is included to handle OCR for the images and PDFs.
-   **RAG Digestion Job:** The `DigestRagUpload` job now handles PDF and image uploads. It uses `PdfToImages` and `ImageToText` to extract text and create document fragments.
-   **UI Updates:**  The RAG uploader component now accepts PDF and image file types if `ai_rag_pdf_images_enabled` is true. The UI text is adjusted to indicate supported file types.

**3. Refactoring and Improvements:**

-   **LLM Enumeration:** The `DiscourseAi::Configuration::LlmEnumerator` now provides a `values_for_serialization` method, which returns a simplified array of LLM data (id, name, vision_enabled) suitable for use in serializers. This avoids exposing unnecessary details to the frontend.
-   **AI Helper:** The `AiHelper::Assistant` now takes optional `helper_llm` and `image_caption_llm` parameters in its constructor, allowing for greater flexibility.
-   **Bot and Persona Updates:** Several updates were made across the codebase, changing the string based association to a LLM to the new model based.
-   **Audit Logs:** The `DiscourseAi::Completions::Endpoints::Base` now formats raw request payloads as pretty JSON for easier auditing.
- **Eval Script:** An evaluation script is included.

**4. Testing:**

-    The PR introduces a new eval system for LLMs, this allows us to test how functionality works across various LLM providers. This lives in `/evals`
* FEATURE: Tool name validation

- Add unique index to the name column of the ai_tools table
- correct our tests for AiToolController
- tool_name field which will be used to represent to LLM
- Add tool_name to Tools's presets
- Add duplicate tools validation for AiPersona
- Add unique constraint to the name column of the ai_tools table

* DEV: Validate duplicate tool_name between builin tools and custom tools

* lint

* chore: fix linting

* fix conlict mistakes

* chore: correct icon class

* chore: fix failed specs

* Add max_length to tool_name

* chore: correct the option name

* lintings

* fix lintings
We have a flag to signal we are shortening the embeddings of a model.
Only used in Open AI's text-embedding-3-*, but we plan to use it for other services.
* Use AR model for embeddings features

* endpoints

* Embeddings CRUD UI

* Add presets. Hide a couple more settings

* system specs

* Seed embedding definition from old settings

* Generate search bit index on the fly. cleanup orphaned data

* support for seeded models

* Fix run test for new embedding

* fix selected model not set correctly
To quickly select backfill candidates without comparing SHAs, we compare the last summarized post to the topic's highest_post_number. However, hiding or deleting a post and adding a small action will update this column, causing the job to stall and re-generate the same summary repeatedly until someone posts a regular reply. On top of this, this is not always true for topics with `best_replies`, as this last reply isn't necessarily included.

Since this is not evident at first glance and each summarization strategy picks its targets differently, I'm opting to simplify the backfill logic and how we track potential candidates.

The first step is dropping `content_range`, which serves no purpose and it's there because summary caching was supposed to work differently at the beginning. So instead, I'm replacing it with a column called `highest_target_number`, which tracks `highest_post_number` for topics and could track other things like channel's `message_count` in the future.

Now that we have this column when selecting every potential backfill candidate, we'll check if the summary is truly outdated by comparing the SHAs, and if it's not, we just update the column and move on
Adds a comprehensive quota management system for LLM models that allows:

- Setting per-group (applied per user in the group) token and usage limits with configurable durations
- Tracking and enforcing token/usage limits across user groups
- Quota reset periods (hourly, daily, weekly, or custom)
-  Admin UI for managing quotas with real-time updates

This system provides granular control over LLM API usage by allowing admins
to define limits on both total tokens and number of requests per group.
Supports multiple concurrent quotas per model and automatically handles
quota resets.


Co-authored-by: Keegan George <[email protected]>
This update adds some structure for handling errors in the spam config while also handling a specific error related to the spam scanning user not being an admin account.
The seeded LLM setting: `SiteSetting.ai_spam_detection_model_allowed_seeded_models` returns a _string_ with IDs separated by pipes. running `_map` on it will return an array with strings. We were previously checking for the id with custom prefix identifier, but instead we should be checking the stringified ID.
- Add spam_score_type to AiSpamSerializer for better integration with reviewables.
- Introduce a custom filter for detecting AI spam false negatives in moderation workflows.
- Refactor spam report generation to improve identification of false negatives.
- Add tests to verify the custom filter and its behavior.
- Introduce links for all spam counts in report
In a previous refactor, we moved the responsibility of querying and storing embeddings into the `Schema` class. Now, it's time for embedding generation.

The motivation behind these changes is to isolate vector characteristics in simple objects to later replace them with a DB-backed version, similar to what we did with LLM configs.
* REFACTOR: A Simpler way of interacting with embeddings' tables.

This change adds a new abstraction called `Schema`, which acts as a repository that supports the same DB features `VectorRepresentation::Base` has, with the exception that removes the need to have duplicated methods per embeddings table.

It is also a bit more flexible when performing a similarity search because you can pass it a block that gives you access to the builder, allowing you to add multiple joins/where conditions.
In this PR, we added functionality to hide the admin header for edit/new actions - https://github.com/discourse/discourse/pull/30175

To make it work properly, we have to rename `show` to `edit` which is also a more accurate name.
 Sam
 Roman Rizzi
 Keegan George

 Hoa Nguyen
 Krzysztof Kotlarek