## 🔍 Overview
When you have a post with audio being played and you open and close the AI post helper menu, it re-renders the entire post DOM, causing the audio to be interrupted and stop playing.

The reason for this is because we highlight the selected text when opening the AI post helper menu and we replace the entire post back with the original post HTML when closing the menu. This fix ensures that we do not re-render the entire post DOM and instead only remove the highlighted section that was added.

## 🔗 Context
https://meta.discourse.org/t/ai-helper-interrupting-uploaded-mp3-audio-stream/366817?u=keegan
* Small fix, reasoning is now available on Claude 4 models

* fix invalid filters should raise, topic filter not working

* fix spec so we are consistent
* FIX: apply diffs more consistently

1. Do escaping direct in diff streamer, that way HTML tags and other unsafe chars can be displayed and fixed
2. Add safeguard to ensure streaming always stops when it was terminated elsewhere

* lint

* bug unsubscribe should unsubscribe
We were getting an error in this logic causing Ember to fail to render the non-bot-topic that we navigate to.

I believe this is because the getter of participants is re-calculating (due to this.header.topicInfo being updated) before the args to this connector changes. Adding some safe navigation here fixes the issue.
* FIX: Improve MessageBus efficiency and correctly stop streaming

This commit enhances the message bus implementation for AI helper streaming by:

- Adding client_id targeting for message bus publications to ensure only the requesting client receives streaming updates
- Limiting MessageBus backlog size (2) and age (60 seconds) to prevent Redis bloat
- Replacing clearTimeout with Ember's cancel method for proper runloop management, we were leaking a stop
- Adding tests for client-specific message delivery

These changes improve memory usage and make streaming more reliable by ensuring messages are properly directed to the requesting client.

* composer suggestion needed a fix as well.

* backlog size of 2 is risky here cause same channel name is reused between clients
**This update includes a variety of small fixes to the AI composer helper:**
- ensures there is no flash of no text when diff modal is triggered
- escapes selected text prior to diff streaming
- uses monospace font in diff modal since text rendered is raw markdown
* FIX: ensures stream update object is scoped to its initial topic

Before this commit you could end up in this situation where a `post-updater` is constructed for a specific topic, but the user changes topic mid steam and it ends up updating the same post number but in a  different topic as we were only checking for `post_number` and not the combination of `topic_id` + `post_number`.

* we should have the topic
Previous to this fix we would diff the entire body of text, this
could lead to situations where a diff presented to a user was
wildly off matching areas in the text that should not have been
tested.

New algorithm only checks a portion of the string, this ensures
that during streaming there is no chance for wild mistakes
The structured output JSON comes embedded inside the API response, which is also a JSON. Since we have to parse the response to process it, any control characters inside the structured output are unescaped into regular characters, leading to invalid JSON and breaking during parsing. This change adds a retry mechanism that escapes
the string again if parsing fails, preventing the parser from breaking on malformed input and working around this issue.

For example:

```
  original = '{ "a": "{\\"key\\":\\"value with \\n newline\\"}" }'
  JSON.parse(original) => { "a" => "{\"key\":\"value with \n newline\"}" }
  # At this point, the inner JSON string contains an actual newline.
```
Generally speaking we never want to do:

```
expect(element.text).to eq("foo")
```

As these are rspec matchers and do not add further Capybara-style waiting specifically for the text content to become present.
Also allow artifact access to current username

Usage inside artifact is:

1. await window.discourseArtifactReady;
2. access data via window.discourseArtifactData;
AI share page assets are loaded via the app CDN, which means the requests have no authentication and will never appear to the app as "logged in". Therefore we should skip the `redirect_to_login_if_required` before_action.
This update adds a safety checker which scans the streamed updates. It ensures that incomplete segments of text are not sent yet over message bus as this will cause breakage with the diff streamer. It also updates the diff streamer to handle a thinking state for when we are waiting for message bus updates.
This change fixes two bugs and adds a safeguard.

The first issue is that the schema Gemini expected differed from the one sent, resulting in 400 errors when performing completions.

The second issue was that creating a new persona won't define a method
for `response_format`. This has to be explicitly defined when we wrap it inside the Persona class. Also, There was a mismatch between the default value and what we stored in the DB. Some parts of the code expected symbols as keys and others as strings.

Finally, we add a safeguard when, even if asked to, the model refuses to reply with a valid JSON. In this case, we are making a best-effort to recover and stream the raw response.
* FEATURE: allow researcher to also research specific topics

Also improve UI around research with more accurate info

* this ensures that under no conditions PMs will be included
* DEV: use a proper object for tool definition

This moves away from using a loose hash to define tools, which
is error prone.

Instead given a proper object we will also be able to coerce the
return values to match tool definition correctly

* fix xml tools

* fix anthropic tools

* fix specs... a few more to go

* specs are passing

* FIX: coerce values for XML tool calls

* Update spec/lib/completions/tool_definition_spec.rb

Co-authored-by: Copilot <[email protected]>

---------

Co-authored-by: Copilot <[email protected]>
This commit introduces a new Forum Researcher persona specialized in deep forum content analysis along with comprehensive improvements to our AI infrastructure.

Key additions:

    New Forum Researcher persona with advanced filtering and analysis capabilities
    Robust filtering system supporting tags, categories, dates, users, and keywords
    LLM formatter to efficiently process and chunk research results

Infrastructure improvements:

    Implemented CancelManager class to centrally manage AI completion cancellations
    Replaced callback-based cancellation with a more robust pattern
    Added systematic cancellation monitoring with callbacks

Other improvements:

    Added configurable default_enabled flag to control which personas are enabled by default
    Updated translation strings for the new researcher functionality
    Added comprehensive specs for the new components

    Renames Researcher -> Web Researcher

This change makes our AI platform more stable while adding powerful research capabilities that can analyze forum trends and surface relevant content.
Examples simulate previous interactions with an LLM and come
right after the system prompt. This helps grounding the model and
producing better responses.
This update improves the animation for streaming a diff of changes when AI helper proofread is triggered. It shows the original text with diff changes live instead of after the fact.
We were logging persona triage as "bot" in logs, causing some
confusions around real world usage

This amends it so we log usage to "automation - AUTOMATION NAME"
* DEV: Use structured responses for summaries

* Fix system specs

* Make response_format a first class citizen and update endpoints to support it

* Response format can be specified in the persona

* lint

* switch to jsonb and make column nullable

* Reify structured output chunks. Move JSON parsing to the depths of Completion

* Switch to JsonStreamingTracker for partial JSON parsing
This ensures webp / gif are converted to png prior to sending
to LLMs given webp and gif are not evenly supported.

png/jpg is universally supported and are the only supported format.

longer term we need to add support for audio/video/pdf which is supported by some models.

* more specs
This PR addresses a bug where uploads weren't being cleared after successfully posting a new private message in the AI bot conversations interface. Here's what the changes do:

## Main Fix:
- Makes the `prepareAndSubmitToBot()` method async and adds proper error handling
- Adds `this.uploads.clear()` after successful submission to clear all uploads
- Adds a test to verify that the "New Question" button properly resets the UI with no uploads

## Additional Improvements:
1. **Dynamic Character Length Validation**:
   - Uses `siteSettings.min_personal_message_post_length` instead of hardcoded 10 characters
   - Updates the error message to show the dynamic character count
   - Adds proper pluralization in the localization file for the error message

2. **Bug Fixes**:
   - Adds null checks with optional chaining (`link?.topic?.id`) in the sidebar code to prevent potential errors

3. **Code Organization**:
   - Moves error handling from the service to the controller for better separation of concerns
System personas leaned on reused classes, this was a problem
in a multisite environement cause state, such as "enabled"
ended up being reused between sites.

New implementation ensures state is pristine between sites in
a multisite

* more handling for new superclass story

* small oversight, display name should be used for display
This commit introduces file upload capabilities to the AI Bot conversations interface and improves the overall dedicated UX experience. It also changes the experimental setting to a more permanent one.

## Key changes:

- **File upload support**:
  - Integrates UppyUpload for handling file uploads in conversations
  - Adds UI for uploading, displaying, and managing attachments
  - Supports drag & drop, clipboard paste, and manual file selection
  - Shows upload progress indicators for in-progress uploads
  - Appends uploaded file markdown to message content

- **Renamed setting**:
  - Changed `ai_enable_experimental_bot_ux` to `ai_bot_enable_dedicated_ux`
  - Updated setting description to be clearer
  - Changed default value to `true` as this is now a stable feature
  - Added migration to handle the setting name change in database

- **UI improvements**:
  - Enhanced input area with better focus states
  - Improved layout and styling for conversations page
  - Added visual feedback for upload states
  - Better error handling for uploads in progress

- **Code organization**:
  - Refactored message submission logic to handle attachments
  - Updated DOM element IDs for consistency
  - Fixed focus management after submission

- **Added tests**:
  - Tests for file upload functionality
  - Tests for removing uploads before submission
  - Updated existing tests to work with the renamed setting


---------

Co-authored-by: awesomerobot <[email protected]>
Invalid access error should be populated to user when trying to search for something they do not have permissions for (i.e. anons searching `in:messages`
This commit adds an empty state when the user doesn't have any PM history. It ALSO retains the new conversation button in the sidebar so it no longer jumps. The button is disabled, icon, and text are all updated.
AI bots come in 2 flavors

1. An LLM and LLM user, in this case we should decorate posts with persona name
2. A Persona user, in this case, in PMs we decorate with LLM name

(2) is a significant improvement, cause previously when creating a conversation
you could not tell which LLM you were talking to by simply looking at the post, you would
have to scroll to the top of the page.

* lint

* translation missing
This commit enhances the AI image generation functionality by adding support for:

1. OpenAI's GPT-based image generation model (gpt-image-1)
2. Image editing capabilities through the OpenAI API
3. A new "Designer" persona specialized in image generation and editing
4. Two new AI tools: CreateImage and EditImage

Technical changes include:
- Renaming `ai_openai_dall_e_3_url` to `ai_openai_image_generation_url` with a migration
- Adding `ai_openai_image_edit_url` setting for the image edit API endpoint
- Refactoring image generation code to handle both DALL-E and the newer GPT models
- Supporting multipart/form-data for image editing requests

* wild guess but maybe quantization is breaking the test sometimes

this increases distance

* Update lib/personas/designer.rb

Co-authored-by: Alan Guo Xiang Tan <[email protected]>

* simplify and de-flake code

* fix, in chat we need enough context so we know exactly what uploads a user uploaded.

* Update lib/personas/tools/edit_image.rb

Co-authored-by: Alan Guo Xiang Tan <[email protected]>

* cleanup downloaded files right away

* fix implementation

---------

Co-authored-by: Alan Guo Xiang Tan <[email protected]>
# Preview

https://github.com/user-attachments/assets/3fe3ac8f-c938-4df4-9afe-11980046944d

# Details

- Group pms by `last_posted_at`. In this first iteration we are group by `7 days`, `30 days`, then by month beyond that.
- I inject a sidebar section link with the relative (last_posted_at) date and then update a tracked value to ensure we don't do it again. Then for each month beyond the first 30days, I add a value to the `loadedMonthLabels` set and we reference that (plus the year) to see if we need to load a new month label.
- I took the creative liberty to remove the `Conversations` section label - this had no purpose
- I hid the _collapse all sidebar sections_ carrot. This had no purpose.
- Swap `BasicTopicSerializer` to `ListableTopicSerializer` to get access to `last_posted_at`
In the last commit, I introduced a topic_custom_field to determine if a PM is indeed a bot PM.

This commit adds a migration to backfill any PM that is between 1 real user, and 1 bot. The correct topic_custom_field is added for these, so they will appear on the bot conversation sidebar properly.

We can also drop the joining to topic_users in the controller for sidebar conversations, and the isPostFromAiBot logic from the sidebar.
* FEATURE: display more places where AI is used

- Usage was not showing automation or image caption in llm list.
- Also: FIX - reasoning models would time out incorrectly after 60 seconds (raised to 10 minutes)

* correct enum not to enumerate non configured models

* FEATURE: implement chat streamer

This implements a basic chat streamer, it provides 2 things:

1. Gives feedback to the user when LLM is generating
2. Streams stuff much more efficiently to client (given it may take 100ms or so per call to update chat)
This PR is a retry of: #1135, where we migrate AiTools form to FormKit. The previous PR accidentally removed code related to setting enum values, and as a result was reverted. This update includes enums correctly along with the previous updates.
Overview
This PR introduces a Bot Homepage that was first introduced at https://ask.discourse.org/.

Key Features:
Add a bot homepage: /discourse-ai/ai-bot/conversations
Display a sidebar with previous bot conversations
Infinite scroll for large counts
Sidebar still visible when navigation mode is header_dropdown
Sidebar visible on homepage and bot PM show view
Add New Question button to the bottom of sidebar on bot PM show view
Add persona picker to homepage
This update adds metrics for estimated spending in AI usage. To make use of it, admins must add cost details to the LLM config page (input, output, and cached input costs per 1M tokens). After doing so, the metrics will appear in the AI usage dashboard as the AI plugin is used.
### 🔍 Overview
This update performs some enhancements to the LLM configuration screen. In particular, it renames the UI for the number of tokens for the prompt to "Context window" since the naming can be confusing to the user. Additionally, it adds a new optional field called "Max output tokens".
Followup fe7e73a6a4 and
1300cc8a36

Reintroduces proofreader specs and unskips ones skipped when
streaming composer suggestions were added. We just need to make sure
the jobs run immediately in specs because the job is what sends the
MessageBus event to the UI.

Also adds a pageobject method to confirm a diff is shown
in the modal before pressing Confirm button.
* FEATURE: Update model names and specs

- not a bug, but made it explicit that tools and thinking are not a chat thing
- updated all models to latest in presets (Gemini and OpenAI)

* allow larger context windows
This core PR must be merged for this to work
https://github.com/discourse/discourse/pull/32280

We want to make sure we don't have regressions with this
functionality in the rich editor, which uses contendeditable
and other APIs than the old composer.
1. Add age of post to topic context (1 month ago, 1 year ago, etc)
2. Refactor code for simplicity
3. Fix handling of post context in DMs which was not using new handling of uploads
Previous to this fix we assumed the name field contained usernames
when in fact it was stored in the id field.

This fixes the context contruction and also adds some basic user
information to the context to assist responders in understanding
the cast of chars
In this feature update, we add the UI for the ability to easily configure persona backed AI-features. The feature will still be hidden until structured responses are complete.
This update fixes a few issues in the split topic suggester. It fixes an issue where not all the category suggestions were appearing in the client. It also fixes an issue where the `move-post` request fails when creating a new topic with only one tag suggestion.
Add API methods to AI tools for reading and updating personas, enabling
more flexible AI workflows. This allows custom tools to:

- Fetch persona information through discourse.getPersona()
- Update personas with modified settings via discourse.updatePersona()
- Also update using persona.update()

These APIs enable new use cases like "trainable" moderation bots, where
users with appropriate permissions can set and refine moderation rules
through direct chat interactions, without needing admin panel access.

Also adds a special API scope which allows people to lean on API
for similar actions

Additionally adds a rather powerful hidden feature can allow custom tools
to inject content into the context unconditionally it can be used for memory and similar features
This update fixes a few small quirks with Discobot discoveries:
- [X] subsequent searches should work correctly
- [X] discovery timeout should maintain UI
- [X] key up/down traversal of regular search results should still work
Previously, allowing "everyone" to access gists meant anons would see them too.
With the move to Personas, we used "[]" to reflect that.

With discourse/discourse#32199 adding the "everyone" option to the personas-allowed
groups, we are switching back to the original behavior.
Leaving allowed groups empty should always mean nobody can use the feature.
We started used a callback as a buffer in FoldContent, so the Fake endpoint is attempting
to emulate delays in the streaming. However, we don't care about that in these specs.
* REFACTOR: Move personas into it's own module.

* WIP: Use personas for summarization

* Prioritize persona default LLM or fallback to newest one

* Simplify summarization strategy

* Keep ai_sumarization_model as a fallback
This feature update allows for continuing the conversation with Discobot Discoveries in an AI bot chat. After discoveries gives you a response to your search you can continue with the existing context.
This change moves all the personas code into its own module. We want to treat them as a building block features can built on top of, same as `Completions::Llm`.

The code to title a message was moved from `Bot` to `Playground`.
* DEV: refactor bot internals

This introduces a proper object for bot context, this makes
it simpler to improve context management as we go cause we
have a nice object to work with

Starts refactoring allowing for a single message to have
multiple uploads throughout

* transplant method to message builder

* chipping away at inline uploads

* image support is improved but not fully fixed yet

partially working in anthropic, still got quite a few dialects to go

* open ai and claude are now working

* Gemini is now working as well

* fix nova

* more dialects...

* fix ollama

* fix specs

* update artifact fixed

* more tests

* spam scanner

* pass more specs

* bunch of specs improved

* more bug fixes.

* all the rest of the tests are working

* improve tests coverage and ensure custom tools are aware of new context object

* tests are working, but we need more tests

* resolve merge conflict

* new preamble and expanded specs on ai tool

* remove concept of "standalone tools"

This is no longer needed, we can set custom raw, tool details are injected into tool calls
**This update makes a few improvements to search discoveries:**
- [x] in search menu panel: search discoveries should still be triggered when no regular results are present
- [x] in full page search: search discoveries should still be triggered when no regular results are present
- [x] flakiness in search discoveries sometimes not working properly.

---------

Co-authored-by: awesomerobot <[email protected]>
* wip: more dynamic availableForcedTools

* FIX: forced tools wasn't set correctly when tool has no options.

---------

Co-authored-by: Roman Rizzi <[email protected]>
The AI Tool spec that checks that the tool runner will not timeout on slow HTTP request is flaky. In this PR we attempt to resolve the flakiness by:

Ensuring stub_request runs before the request
Increasing the timeout for CI env
This takes the logic used in summarization/discoveries for streaming and consolidates it into a single helper lib for smooth streaming. It introduces a new lib: `SmoothStreamer` that can be used by components for smooth streaming text from message bus updates. Additionally, the PR makes use of that new lib in the AI post menu helper.
The older design approach for sentiment analysis report needed the click outside logic. However, when the design was changed this logic was accidentally left behind. It is potentially causing some negative performance impacts. This PR removes the old unnecessary logic.
This PR ensures that the category badges are present in the sentiment analysis report. Since the core change in https://github.com/discourse/discourse/pull/31795, there was a regression in the post list drill-down where category badges were not being shown. This PR fixes that and also ensures icons/emojis are shown when categories make use of them. This PR also adds the category badge in the table list.
This update fixes an issue where the results of the post helper menu was not selectable. Previously, selecting any text inside the menu was immediately closing the menu.
The sentiment analysis report page initially showcases sentiments via category/tag by doughnut visualizations. However, this isn't an optimal view for quickly scanning and comparing each result. This PR updates the overview to include a table visualization with horizontal bars to represent sentiment analysis instead of doughnuts. Doughnut visualizations are still maintained however when accessing the sentiment data in the drill down for individual entries.

This approach is an intermediary step, as we will eventually add whole clustering and sizing visualization instead of a table. As such, no relevant tests are added in this PR.
This PR adds support for disabling further tool calls by setting tool_choice to :none across all supported LLM providers:

- OpenAI: Uses "none" tool_choice parameter
- Anthropic: Uses {type: "none"} and adds a prefill message to prevent confusion
- Gemini: Sets function_calling_config mode to "NONE"
- AWS Bedrock: Doesn't natively support tool disabling, so adds a prefill message

We previously used to disable tool calls by simply removing tool definitions, but this would cause errors with some providers. This implementation uses the supported method appropriate for each provider while providing a fallback for Bedrock.

Co-authored-by: Natalie Tay <[email protected]>

* remove stray puts

* cleaner chain breaker for last tool call (works in thinking)

remove unused code

* improve test

---------

Co-authored-by: Natalie Tay <[email protected]>
This PR fixes an issue where you are unable to click to see the sentiment drill-down when there are no current filters applied. This is due to trying to `JSON.parse()` the filters when there are no filters. This fix ensures there are filters first before trying to parse the JSON.
* REFACTOR: Migrate Personas' form to FormKit

We re-arranged fields into sections so we can better differentiate which options are specific to the AI bot.

* few form-kit improvements

https://github.com/discourse/discourse/pull/31934

---------

Co-authored-by: Joffrey JAFFEUX <[email protected]>
form.Object and form.Collection have been changed. Most importantly formObject doesnt yield name but data. It's not your responsibility to build an array of fields.
This allows for a new mode in persona triage where nothing is posted on topics.

This allows people to perform all triage actions using tools

Additionally introduces new APIs to create chat messages from tools which can be useful in certain moderation scenarios

Co-authored-by: Natalie Tay <[email protected]>

* remove TODO code

---------

Co-authored-by: Natalie Tay <[email protected]>
When editing a topic (instead of creating one) and using the
tag/category suggestion buttons. We want to use existing topic
embeddings instead of creating new ones.
- Fix search API to only include column_names when present to make the API less confusing
- Ensure correct LLM is used in PMs by tracking and preferring the last bot user
- Fix persona_id conversion from string to integer in custom fields
- Add missing test for PM triage with no replies - ensure we don't try to auto title topic
- Ensure bot users are properly added to PMs
- Make title setting optional when replying to posts
- Add ability to control stream_reply behavior

These changes improve reliability and fix edge cases in bot interactions,
particularly in private messages with multiple LLMs and while triaging posts using personas
thinking models such as Claude 3.7 Thinking and o1 / o3 do not
support top_p or temp.

Previously you would have to carefully remove it from everywhere
by having it be a provider param we now support blanker removing
without forcing people to update automation rules or personas
When spam scanner is enabled and code is reloaded, developer experience this error:

```
NameError at /posts
===================

uninitialized constant DiscourseAi::AiModeration::EntryPoint::SpamScanner

> To access an interactive console with this error, point your browser to: /__better_errors

plugins/discourse-ai/lib/ai_moderation/entry_point.rb, line 7
```

It is because when we call `SpamScanner` it is searched within parent `DiscourseAi::AiModeration::EntryPoint` namespace.

We can help a bit Zeitwerk by calling SpamScanner more explicitly.
This update adds the ability to disable search discoveries. This can be done through a tooltip when search discoveries are shown. It can also be done in the AI user preferences, which has also been updated to accommodate more than just the one image caption setting.
### ✨ What's new?
- [X] show sentiment counts by color on doughnut without needing to hover
- [X] minor UI padding adjustments
- [X] hide filters that are not allowed to be adjusted in selected chart view
- [X] fix z-index issues with drill-down filters
Adds a new rake task to generate topics using the AI helper model.
Generate topics using
```
bundle exec rake "ai:generate_topics[Don Quijote de la Mancha\, Cien años de soledad\, Os Lusíadas\,三国演义]"
```
For now it randomly chooses a non-read-restricted category and a random bunch of users.
This PR enhances the LLM triage automation with several important improvements:
- Add ability to use AI personas for automated replies instead of canned replies
- Add support for whisper responses
- Refactor LLM persona reply functionality into a reusable method
- Add new settings to configure response behavior in automations
- Improve error handling and logging
- Fix handling of personal messages in the triage flow
- Add comprehensive test coverage for new features
- Make personas configurable with more flexible requirements
This allows for more dynamic and context-aware responses in automated workflows, with better control over visibility and attribution.
## LLM Persona Triage
- Allows automated responses to posts using AI personas
- Configurable to respond as regular posts or whispers
- Adds context-aware formatting for topics and private messages
- Provides special handling for topic metadata (title, category, tags)
## LLM Tool Triage
- Enables custom AI tools to process and respond to posts
- Tools can analyze post content and invoke personas when needed
- Zero-parameter tools can be used for automated workflows
- Not enabled in production yet
## Implementation Details
- Added new scriptable registration in discourse_automation/ directory
- Created core implementation in lib/automation/ modules
- Enhanced PromptMessagesBuilder with topic-style formatting
- Added helper methods for persona and tool selection in UI
- Extended AI Bot functionality to support whisper responses
- Added rate limiting to prevent abuse
## Other Changes
- Added comprehensive test coverage for both automation types
- Enhanced tool runner with LLM integration capabilities
- Improved error handling and logging
This feature allows forum admins to configure AI personas to automatically respond to posts based on custom criteria and leverage AI tools for more complex triage workflows.
Tool Triage has been disabled in production while we finalize details of new scripting capabilities.
**This PR includes a variety of updates to the Sentiment Analysis report:**
- [X] Conditionally showing sentiment reports based on `sentiment_enabled` setting
- [X] Sentiment reports should only be visible in sidebar if data is in the reports
- [X] Fix infinite loading of posts in drill down
- [x] Fix markdown emojis showing not showing as emoji representation
- [x] Drill down of posts should have URL
- [x] ~~Different doughnut sizing based on post count~~ [reverting and will address in follow-up (see: `/t/146786/47`)]
- [X] Hide non-functional export button
- [X] Sticky drill down filter nav
adds support for "thinking tokens" - a feature that exposes the model's reasoning process before providing the final response. Key improvements include:
- Add a new Thinking class to handle thinking content from LLMs
- Modify endpoints (Claude, AWS Bedrock) to handle thinking output
- Update AI bot to display thinking in collapsible details section
- Fix SEARCH/REPLACE blocks to support empty replacement strings and general improvements to artifact editing
- Allow configurable temperature in triage and report automations
- Various bug fixes and improvements to diff parsing
## 🔍 Overview
This update ensures that the streaming for discoveries is smoother, especially on first update.
## ➕ More details
To help with smoother streaming, the discovery preview (which was being tracked as a separate property in the JS logic) will be removed and the entire discovery content will be shown/hidden via the existing CSS. The preview was already receiving the full update even though it was visually hidden, so removing the separate property shouldn't have any negative performance hit. Visually hiding it with CSS only will help simplify the component and also allow for smoother streaming. We will instead remove the buffered streaming approach and instead use typing timers similar to what we did for streaming summarization.
No related tests as streaming animations are difficult to test.
This update improves some of the UI around sentiment analysis reports:
1. Improve titles so it is above and truncated when long
2. Change doughnut to only show total count
3. Ensures sentiment posts have dates
4. Ensure expand post doesn't appear on short posts
* FEATURE: full support for Sonnet 3.7
- Adds support for Sonnet 3.7 with reasoning on bedrock and anthropic
- Fixes regression where provider params were not populated
Note. reasoning tokens are hardcoded to minimum of 100 maximum of 65536
* FIX: open ai non reasoning models need to use deprecate max_tokens
* FIX: legacy reasoning models not working, missing provider params
1. Legacy reasoning models (o1-preview / o1-mini) do not support developer or system messages, do not use them.
2. LLM editor form not showing all provider params due to missing remap
* add system test
* FEATURE: Experimental search results from an AI Persona.
When a user searches discourse, we'll send the query to an AI Persona to provide additional context and enrich the results. The feature depends on the user being a member of a group to which the persona has access.
* Update assets/stylesheets/common/ai-blinking-animation.scss
Co-authored-by: Keegan George <[email protected]>
---------

Co-authored-by: Keegan George <[email protected]>
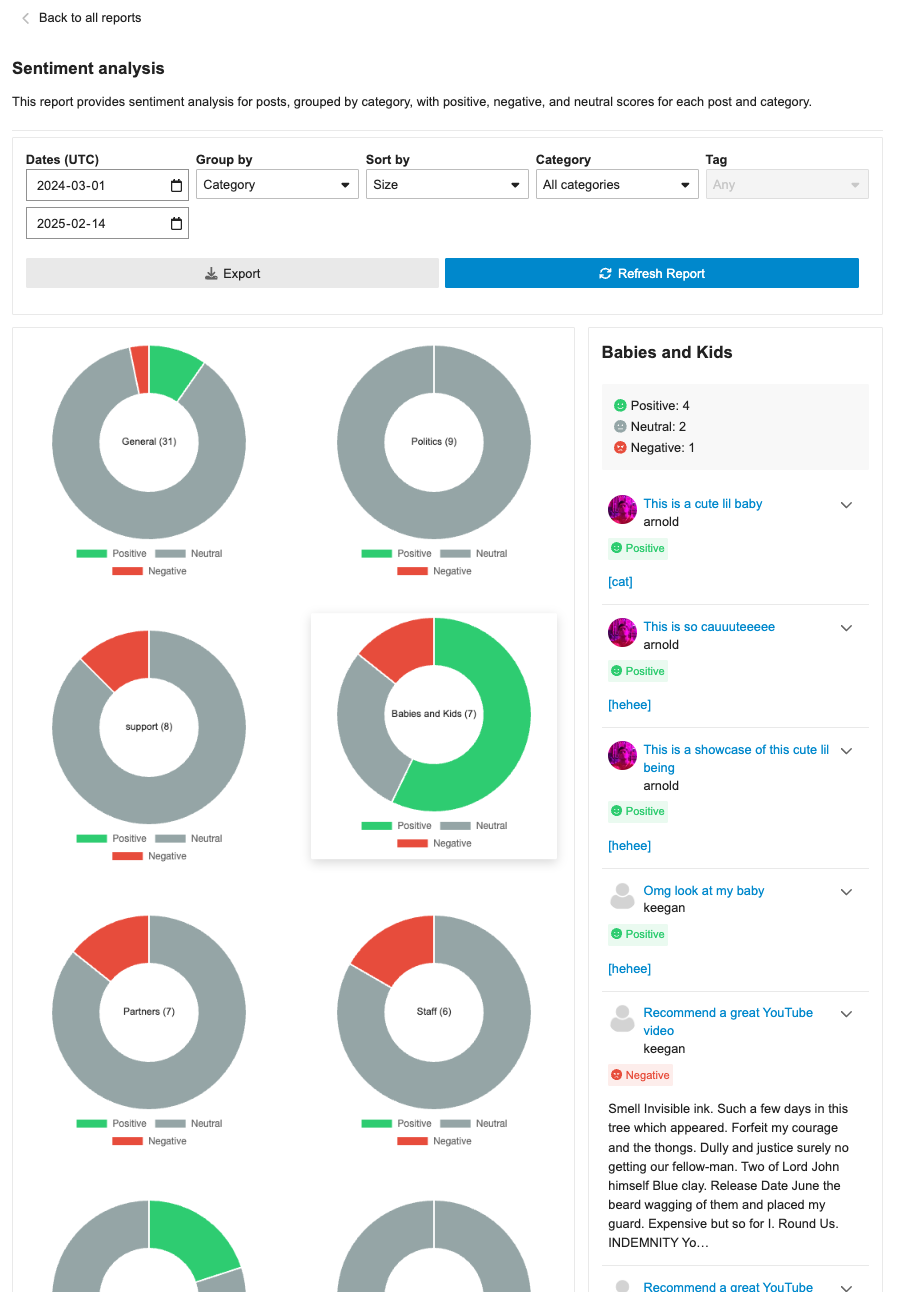
## 🔍 Overview
This update adds a new report page at `admin/reports/sentiment_analysis` where admins can see a sentiment analysis report for the forum grouped by either category or tags.
## ➕ More details
The report can breakdown either category or tags into positive/negative/neutral sentiments based on the grouping (category/tag). Clicking on the doughnut visualization will bring up a post list of all the posts that were involved in that classification with further sentiment classifications by post.
The report can additionally be sorted in alphabetical order or by size, as well as be filtered by either category/tag based on the grouping.
## 👨🏽💻 Technical Details
The new admin report is registered via the pluginAPi with `api.registerReportModeComponent` to register the custom sentiment doughnut report. However, when each doughnut visualization is clicked, a new endpoint found at: `/discourse-ai/sentiment/posts` is fetched to showcase posts classified by sentiments based on the respective params.
## 📸 Screenshots
The require for `discourse/config/environment` should point to the local user's core Discourse environment instead of the hardcoded path for Sam's env.
From [pgvector/pgvector](https://github.com/pgvector/pgvector) README

> With approximate indexes, filtering is applied after the index is scanned. If a condition matches 10% of rows, with HNSW and the default hnsw.ef_search of 40, only 4 rows will match on average. For more rows, increase hnsw.ef_search.
>
> Starting with 0.8.0, you can enable [iterative index scans](https://github.com/pgvector/pgvector#iterative-index-scans), which will automatically scan more of the index when needed.


Since we are stuck on 0.7.0 we are going the first option for now.
- Add non-contiguous search/replace support using ... syntax
- Add judge support for evaluating LLM outputs with ratings
- Improve error handling and reporting in eval runner
- Add full section replacement support without search blocks
- Add fabricators and specs for artifact diffing
- Track failed searches to improve debugging
- Add JS syntax validation for artifact versions in eval system
- Update prompt documentation with clear guidelines

* improve eval output

* move error handling

* llm as a judge

* fix spec

* small note on evals
Some files were not shown because too many files have changed in this diff
Show More
Reference in New Issue
Block a user
Blocking a user prevents them from interacting with repositories, such as opening or commenting on pull requests or issues. Learn more about blocking a user.
 Jordan Vidrine
 Discourse Translator Bot
 Sam
 Keegan George
 Mark VanLandingham
 Jordan Vidrine
 Roman Rizzi
 Joffrey JAFFEUX
 Kris
 Guhyoun Nam
 David Taylor

 dependabot[bot]
 Rafael dos Santos Silva
 Isaac Janzen
 Alan Guo Xiang Tan

 Sérgio Saquetim
 Renato Atilio
 Martin Brennan
 Loïc Guitaut

 Natalie Tay
 Régis Hanol
 Jarek Radosz
 Penar Musaraj
 Kelv
 Ted Johansson