This index helps to speed up queries that joins the `topics` table
against the `ai_topics_embeddings` table on the `topic_id` column. There
are a number of queries which filters on `ai_topics_embeddings.model_id`
so we are including that in the index as well.
We enforced a hard limit of 700 tokens in this script, which is not enough when using thinking models, which can quickly use all of them.

A temporary solution could be bumping the limit, but there is no guarantee we won't hit it again, and it's hard to find one value that fits all scenarios. Another alternative could be removing it and relying on the LLM config's `max_output_token`, but if you want different rules and want to assign different limits, you are forced to duplicate the config each time.

Considering all this, we are adding a dedicated field for this in the triage script, giving you an easy way to tweak it to your needs. If empty, no limit is applied.
We're seeing that some LLMs are using 65000+ tokens for raw text that is only 10-1000 characters long.

This PR adds a max_token to be passed to the LLM API for each translation based on the length of the text.
Since we use the value for days.ago and are seeing PG::DatetimeFieldOverflow: ERROR: timestamp out of range: "5473790-07-13 08:43:28.497823 BC, set limits to the site setting.
Since translations only require a single key back, there is little point in using structured output. This PR also includes some prompt updates dealing with quotes, details, and code.

Related: #1502

This does mean reverting discourse/discourse-translator#257, but we can see how it goes.
Structured outputs are prone to formatting issue, especially around newlines
and custom pieces of text that need escaping.

This avoids using it for the automation reporting.

Particularly previous to this fix o4-mini based reports were broken
Try fix a flaky spec in /ai_bot/homepage_spec.rb by using ember
data rather than inspecting the DOM directly to see if there
are any in-progress uploads.

Also add missing translation for in progress uploads warning.
This commit
- normalizes locales like en_GB and variants to en. With this, the feature will not translate en_GB posts to en (or similarly pt_BR to pt_PT)
- consolidates whether the feature is enabled in `DiscourseAi::Translation.enabled?`
- similarly for backfill in  `DiscourseAi::Translation.backfill_enabled?`
  - turns off backfill if `ai_translation_backfill_max_age_days` is 0 to keep true to what it says. Set it to a high number to backfill everything
This update ensures that the `topic_id` related to the error when summarizing is surfaced in the logs, which should help track down the reason for the errors.
This update fixes a regression from https://github.com/discourse/discourse-ai/pull/1484, which caused AI helper title suggestions to begin suggesting numerous non-unique titles because it was looping through structured responses incorrectly.
* FIX: make AI helper more robust

- If JSON is broken for structured output then lean on a more forgiving parser
- Gemini 2.5 flash does not support temp, support opting out
- Evals for assistant were broken, fix interface
- Add some missing LLMs
- Translator was not mapped correctly to the feature - fix that
- Don't mix XML in prompt for translator

* lint

* correct logic

* simplify code

* implement best effort json parsing direct in the structured output object
A more deterministic way of making sure the LLM detects the correct language (instead of relying on prompt to LLM to ignore it) is to take the cooked and remove unwanted elements.

In this commit
- we remove quotes, image captions, etc. and only take the remaining text, falling back to the unadulterated cooked
- and update prompts related to detection and translation
- /152465/12
Previous to this change we reused channels for proofreading progress and
ai helper progress

The new changeset ensures each POST to stream progress gets a dedicated
message bus channel

This fixes a class of issues where the wrong information could be displayed
to end users on subsequent proofreading or helper calls

* fix tests

* fix implementation (got to subscribe at 0)
Introducing a typo isn't the right way to bypass the check that blocks the term "private messages".

Nice try, though ;)

I changed it to "personal messages".
When an invalid model is set for embeddings, topics do not load even if embeddings is disabled.

Error:
## RuntimeError in TopicsController#show
Invalid embeddings selected model

This commit checks for valid settings before attempting to load related topics.
* FIX: normalize keys in structured output

Previously we did not validate the hash passed in to structured
outputs which could either be string based or symbol base

Specifically this broke structured outputs for Gemini in some
specific cases.

* comment out flake
- allows features to have multiple llms and multiple personas
- sorts module list
- adds Bot as a first class module
- fixes issue where search module was always configured
- some tests
- Add support for `chain.streamCustomRaw(test)` that can be used to stream text from a JS tool direct to composer
- Add support for llm params in `llm.generate` which unlocks stuff like structured outputs
- Add discourse.createStagedUser, discourse.createTopic  and discourse.createPost - for content creation
* FIX: A typo in bot filtration in ai-bot-header-icon

* FIX: Show header icon when there's only one persona with a default LLM set

---------

Co-authored-by: Roman Rizzi <[email protected]>
Introduces import/export feature for tools and personas.

Uploads are omitted for now, and will be added in a future PR

*   **Backend:**
    *   Adds `import` and `export` actions to `Admin::AiPersonasController` and `Admin::AiToolsController`.
    *   Introduces `DiscourseAi::PersonaExporter` and `DiscourseAi::PersonaImporter` services to manage JSON serialization and deserialization.
    *   The export format for a persona embeds its associated custom tools. To ensure portability, `AiTool` references are serialized using their `tool_name` rather than their internal database `id`.
    *   The import logic detects conflicts by name. A `force=true` parameter can be passed to overwrite existing records.

*   **Frontend:**
    *   `AiPersonaListEditor` and `AiToolListEditor` components now include an "Import" button that handles file selection and POSTs the JSON data to the respective `import` endpoint.
    *   `AiPersonaEditorForm` and `AiToolEditorForm` components feature an "Export" button that triggers a download of the serialized record.
    *   Handles import conflicts (HTTP `409` for tools, `422` for personas) by showing a `dialog.confirm` prompt to allow the user to force an overwrite.

*   **Testing:**
    *   Adds comprehensive request specs for the new controller actions (`#import`, `#export`).
    *   Includes unit specs for the `PersonaExporter` and `PersonaImporter` services.
* Persona import and export implemented
In discourse/discourse-translator#249 we introduced splitting content (post.raw) prior to sending to translation as we were using a sync api.

Now that we're streaming thanks to #1424, we'll chunk based on the LlmModel.max_output_tokens.
In the earlier PR https://github.com/discourse/discourse-ai/pull/1432, when `SiteSetting.ai_translation_backfill_limit_to_public_content = false`, we **translate** PMs but **skip translating** PMs that do not involve groups.

This commit covers the missing case on **locale detection**.
This update replaces deprecated integer duration with standardized duration of either `short` or `long` throughout the plugin usages of `FloatKit` toasts.
This update fixes an issue where the AI user preferences tab was not appearing unless `SiteSetting.ai_helper_enabled` was `true`. This is because we previously checked for it's presence when user preferences only had a single setting related to Helper. However, since then, we've also added search discoveries setting there too. As such, we don't want it to depend on Helper. We also sneak in this update a modernization of converting the preferences template from `.hbs` to `.gjs`.
New implementation uses core concurrent job queue, it is more
robust and predictable than the one shipped in Concurrent.

Additionally:

- Trickles through updates during bulk classification
- Reports errors if we fail during a bulk classification

* push concurrency down to 40. 100 feels quite high.
## 🔍 Overview
This update fixes an issue where message bus streaming related specs
were not working correctly. To do so we pass the `last_id` when
subscribing to `MessageBus` which allows us to unskip those broken
tests.

---------

Co-authored-by: Joffrey JAFFEUX <[email protected]>
The current menu was rendering inside the post text toolbar (on desktop). This is not ideal as the post text toolbar rendering is conditioned on the presence of text selection, when you click a button on the toolbar, by design of the web browsers you will lose your text selection, making all of this super tricky.

This commit makes desktop and mobile behave in the same way by rendering their own menu and capturing the quote state when we render the post text selection toolbar, this allows us to reason a much simpler way about the AI helper.

This commit also removes what appears to be an unused file and corrects which was seemingly copy/paste mistakes.

⚠️ Technical note, this commit is correcting the message bus subscription which amongst other things allows to write specs which are not flaky. However due to the current implementation we have a channel per post, which means we need to serialize on last message bus id per post.

We have two possible solutions here:
- subscribe at the topic level
- refactor the code to be able to use `MessageBus.last_ids` to be able to grab multiple posts at once instead of having to call `MessageBus.last_id` and done one Redis call per post

---------

Co-authored-by: Keegan George <[email protected]>
* FIX: implement max_output tokens (anthropic/openai/bedrock/gemini/open router)

Previously this feature existed but was not implemented
Also updates a bunch of models to in our preset to point to latest

* implementing in base is safer, simpler and easier to manage

* anthropic 3.5 is getting older, lets use 4.0 here and fix spec
This update fixes a UX issue on the AI bot conversations page where the persona selector dropdown doesn't scroll when there are many items and the viewport is small.

No tests as it's tricky to test scrolling.
We're seeing an aggressive number of translations being enqueued for a single post and locale. Historically, we trigger translation on `cooked` not `raw`, but that has changed a while back.

```
# from AiApiAuditLog, the same post is getting translated to the same locale within a few secs of each other
zh_CN - 2025-06-17 13:02:31 UTC
zh_CN - 2025-06-17 13:02:34 UTC
zh_CN - 2025-06-17 13:02:35 UTC
zh_CN - 2025-06-17 13:02:36 UTC
zh_CN - 2025-06-17 13:02:38 UTC
zh_CN - 2025-06-17 13:02:39 UTC
zh_CN - 2025-06-17 13:02:40 UTC
zh_CN - 2025-06-17 13:02:40 UTC
zh_CN - 2025-06-17 13:02:43 UTC
zh_CN - 2025-06-17 13:02:44 UTC
```

This PR prevents this from happening.
This update ensures that we reset the tracked properties when closing the DiffModal so that the state doesn't leak when triggering the AI suggestions again. We also reset before suggesting new changes, thus if regeneration is called there shouldn't be any leaks either.

No tests in this PR as tests currently not working great due to streaming/animation issues. Will do a broader PR following up with various specs to improve test coverage here.
Previously staff and bots would get scanned if TL was low
Additionally if somehow spam scanner user was blocked
(deactivated, silenced, banned) it would stop the feature from working

This adds an override that ensures unconditionally the user is setup correctly prior to scanning
is update adds logging for changes made in the AI admin panel. When making configuration changes to Embeddings, LLMs, Personas, Tools, or Spam that aren't site setting related, changes will now be logged in Admin > Logs & Screening. This will help admins debug issues related to AI. In this update a helper lib is created called `AiStaffActionLogger` which can be easily used in the future to add logging support for any other admin config we need logged for AI.
We want to avoid translating PMs that are not group PMs. This condition is applied when `SiteSetting.ai_translation_backfill_limit_to_public_content = false`
In hybrid mode ai artifacts can optionally automatically run.

This is useful for cases where you may want to embed a survey and so on.

Additionally, artifacts now allow for better fidelity around display:

<div class="ai-artifact" data-ai-artifact-id="501" data-ai-artifact-height="300px" data-ai-artifact-autorun data-ai-artifact-seamless></div>

User can supply height and seamless mode to be seamlessly rendered with no box shadow and show full screen button.
* FIX: improve transition logic in forms

previously back button would take you back to the /new route

* FIX: enum selection not working for persona tools

* seed information correctly in the DB

* fix broken spec

* Update assets/javascripts/discourse/components/ai-tool-editor-form.gjs

Co-authored-by: Alan Guo Xiang Tan <[email protected]>

---------

Co-authored-by: Alan Guo Xiang Tan <[email protected]>
## 🔍  Overview
When the title suggestions return no suggestions, there is no indication in the UI. In the tag suggester we show a toast when there aren't any suggestions but the request was a success. In this update we make a similar UI indication with a toast for both category and title suggestions. Additionally, for all suggestions we add a "Try again" button to the toast so that suggestions can be generated again if the results yield nothing the first time.
Previously we had a logic error and were showing admins keys
that are not theirs when querying for all keys

This makes the API cleaner, to get all results you need to be explicit always
OpenAI ship a new API for completions called "Responses API"

Certain models (o3-pro) require this API.
Additionally certain features are only made available to the new API.

This allow enabling it per LLM.

see: https://platform.openai.com/docs/api-reference/responses
We will fine tune updating an outdated localization in the future. For now we are seeing that quick edits are happening and we need to prevent the job from being too trigger-happy.
Introduces a persistent, user-scoped key-value storage system for
AI Artifacts, enabling them to be stateful and interactive. This
transforms artifacts from static content into mini-applications that can
save user input, preferences, and other data.

The core components of this feature are:

1.  **Model and API**:
    - A new `AiArtifactKeyValue` model and corresponding database table to
      store data associated with a user and an artifact.
    - A new `ArtifactKeyValuesController` provides a RESTful API for
      CRUD operations (`index`, `set`, `destroy`) on the key-value data.
    - Permissions are enforced: users can only modify their own data but
      can view public data from other users.

2.  **Secure JavaScript Bridge**:
    - A `postMessage` communication bridge is established between the
      sandboxed artifact `iframe` and the parent Discourse window.
    - A JavaScript API is exposed to the artifact as `window.discourseArtifact`
      with async methods: `get(key)`, `set(key, value, options)`,
      `delete(key)`, and `index(filter)`.
    - The parent window handles these requests, makes authenticated calls to the
      new controller, and returns the results to the iframe. This ensures
      security by keeping untrusted JS isolated.

3.  **AI Tool Integration**:
    - The `create_artifact` tool is updated with a `requires_storage`
      boolean parameter.
    - If an artifact requires storage, its metadata is flagged, and the
      system prompt for the code-generating AI is augmented with detailed
      documentation for the new storage API.

4.  **Configuration**:
    - Adds hidden site settings `ai_artifact_kv_value_max_length` and
      `ai_artifact_max_keys_per_user_per_artifact` for throttling.

This also includes a minor fix to use `jsonb_set` when updating
artifact metadata, ensuring other metadata fields are preserved.
Additional changes:

Adds a "#features" method in AiPersona to find which features are using that persona.
Serializes a basic version of a LlmModel in the persona's "#default_llm" serializer attribute.
* FEATURE: Display features that rely on multiple personas.

This change makes the previously hidden feature page visible while displaying features, like the AI helper, which relies on multiple personas.

* Fix system specs
## 🔍 Overview
This update re-introduces the validator used on the `ai_spam_detection_enabled` setting. It was initially added here: https://github.com/discourse/discourse-ai/pull/1374 to prevent Spam from being enabled without creating an `AiModerationSetting` value in the database. However, due to issues with backups/migrations we temporarily removed it here: https://github.com/discourse/discourse-ai/pull/1393. Now with some internal fixes, we can re-introduce it. We also update the validator so that it only validates when trying to turn on rather than when turning off too.
The AiApiAuditLog per translation event doesn't trace back easily to a post or topic.

This commit adds support to that, and also switches the translators to named arguments rather than positional arguments.
Previously I had omitted to add `locale` to the category, as categories tended to be just a single word, and I did not find it would be worth to carry locale information.

Due to certain LLMs that do poorer at translation, category descriptions got pretty messy. We added locale support here - https://github.com/discourse/discourse/pull/32962.

This PR adds the automatic locale detection, and skips translating to the category's locale.
This commit changes the RAG uploader form elements to
be @format="full" instead of doing a hardcoded 500px width,
which was causing a horizontal scrollbar in the tools form
on mobile.

Also, it moves the 80% max width for the tools form into the
new viewport CSS API, and only applies it on desktop, because
this was also causing width issues on mobile.
Adds context length controls to researcher (max tokens per post and batch)
Allow picking LLM for researcher
Fix bug where unicode usernames were not working
Fix documentation of OR logic
- add sleep function for tool polling with rate limits
- Support base64 encoding for HTTP requests and uploads
-  Enhance forum researcher with cost warnings and comprehensive planning
- Add cancellation support for research operations
- Include feature_name parameter for bot analytics
- richer research support (OR queries)
* FEATURE: add inferred concepts system

This commit adds a new inferred concepts system that:
- Creates a model for storing concept labels that can be applied to topics
- Provides AI personas for finding new concepts and matching existing ones
- Adds jobs for generating concepts from popular topics
- Includes a scheduled job that automatically processes engaging topics

* FEATURE: Extend inferred concepts to include posts

* Adds support for concepts to be inferred from and applied to posts
* Replaces daily task with one that handles both topics and posts
* Adds database migration for posts_inferred_concepts join table
* Updates PersonaContext to include inferred concepts


Co-authored-by: Roman Rizzi <[email protected]>
Co-authored-by: Keegan George <[email protected]>
This is showing as the most expensive CSS selector in Discourse at the moment. Adding specific classes and dropping the general `span` selector will make this much cheaper.
## 🔍 Overview

When exporting an Overall Sentiment report in the admin panel, the export fails with:

```ruby
Job exception: no implicit conversion of Symbol into Integer
```

This was happening because we are passing a single _Hash_ to `report.data` however, exports expect `report.data` to be an _Array of Hashes_. This update fixes this issue by wrapping the data in an array.
This update includes a variety of small refinements to the AI composer helper:

- prevent height jump when going from loading text placeholder → proofreading text streaming
- update padding on AI helper options list to be more suitable with typical Discourse menu design
- for composer helper results that are not `showResultAsDiff` (i.e. translation):
   - update before/after diff design to be more subtle
   - results should be in normal font (as the text is cooked and not raw markdown)
- fix: smooth streaming animation stuck showing dot icon even after smooth streaming is done
* FEATURE: support upload.getUrl in custom tools

Some tools need to share images with an API. A common pattern
is for APIs to expect a URL.

This allows converting upload://123123 to a proper CDN friendly
URL from within a custom tool

* no support for secure uploads, so be explicit about it.
* FEATURE: simplify streaming implementation - rush last update

Previous to this change we would simply "flash" the final update
on the screen, this amends it so we quickly update the UI in about
1 second in the end with all the final update.

This makes the UI feel more interactive to end users.

* DEV: Updates...

- Remove unnecessary comments
- Add doc style comments for all methods
- Organize methods (private at bottom)
- Update some variable names

---------

Co-authored-by: Keegan George <[email protected]>
Related: https://github.com/discourse/discourse-translator/pull/310

This commit includes all the jobs and event hooks to localize posts, topics, and categories.

A few notes:
- `feature_name: "translation"` because the site setting is `ai-translation` and module is `Translation`
- we will switch to proper ai-feature in the near future, and can consider using the persona_user as `localization.localizer_user_id`
- keeping things flat within the module for now as we will be moving to ai-feature soon and have to rearrange
- Settings renamed/introduced are:
  - ai_translation_backfill_rate (0)
  - ai_translation_backfill_limit_to_public_content (true)
  - ai_translation_backfill_max_age_days (5)
  - ai_translation_verbose_logs (false)
Since we enable/disable `ai_spam_detection_enabled` setting in a custom Spam tab UI in AI, we want to ensure we retain the setting and logging features. To preserve that, we want to update the controller to use `SiteSetting.set_and_log` instead of setting the value directly.
## 🔍 Overview
We want to unhide `ai_spam_detection_enabled` setting so that we can retain staff action log features. However, we also want to ensure users cannot enable spam detection without having `AiModerationSetting.spam` present in the database.

In this update we unhide the setting, but also add a validator to ensure the necessary configuration is in place before allowing the setting to be enabled.
## 🔍 Overview
When you have a post with audio being played and you open and close the AI post helper menu, it re-renders the entire post DOM, causing the audio to be interrupted and stop playing.

The reason for this is because we highlight the selected text when opening the AI post helper menu and we replace the entire post back with the original post HTML when closing the menu. This fix ensures that we do not re-render the entire post DOM and instead only remove the highlighted section that was added.

## 🔗 Context
https://meta.discourse.org/t/ai-helper-interrupting-uploaded-mp3-audio-stream/366817?u=keegan
* Small fix, reasoning is now available on Claude 4 models

* fix invalid filters should raise, topic filter not working

* fix spec so we are consistent
* FIX: apply diffs more consistently

1. Do escaping direct in diff streamer, that way HTML tags and other unsafe chars can be displayed and fixed
2. Add safeguard to ensure streaming always stops when it was terminated elsewhere

* lint

* bug unsubscribe should unsubscribe
We were getting an error in this logic causing Ember to fail to render the non-bot-topic that we navigate to.

I believe this is because the getter of participants is re-calculating (due to this.header.topicInfo being updated) before the args to this connector changes. Adding some safe navigation here fixes the issue.
* FIX: Improve MessageBus efficiency and correctly stop streaming

This commit enhances the message bus implementation for AI helper streaming by:

- Adding client_id targeting for message bus publications to ensure only the requesting client receives streaming updates
- Limiting MessageBus backlog size (2) and age (60 seconds) to prevent Redis bloat
- Replacing clearTimeout with Ember's cancel method for proper runloop management, we were leaking a stop
- Adding tests for client-specific message delivery

These changes improve memory usage and make streaming more reliable by ensuring messages are properly directed to the requesting client.

* composer suggestion needed a fix as well.

* backlog size of 2 is risky here cause same channel name is reused between clients
**This update includes a variety of small fixes to the AI composer helper:**
- ensures there is no flash of no text when diff modal is triggered
- escapes selected text prior to diff streaming
- uses monospace font in diff modal since text rendered is raw markdown
* FIX: ensures stream update object is scoped to its initial topic

Before this commit you could end up in this situation where a `post-updater` is constructed for a specific topic, but the user changes topic mid steam and it ends up updating the same post number but in a  different topic as we were only checking for `post_number` and not the combination of `topic_id` + `post_number`.

* we should have the topic
Previous to this fix we would diff the entire body of text, this
could lead to situations where a diff presented to a user was
wildly off matching areas in the text that should not have been
tested.

New algorithm only checks a portion of the string, this ensures
that during streaming there is no chance for wild mistakes
The structured output JSON comes embedded inside the API response, which is also a JSON. Since we have to parse the response to process it, any control characters inside the structured output are unescaped into regular characters, leading to invalid JSON and breaking during parsing. This change adds a retry mechanism that escapes
the string again if parsing fails, preventing the parser from breaking on malformed input and working around this issue.

For example:

```
  original = '{ "a": "{\\"key\\":\\"value with \\n newline\\"}" }'
  JSON.parse(original) => { "a" => "{\"key\":\"value with \n newline\"}" }
  # At this point, the inner JSON string contains an actual newline.
```
Generally speaking we never want to do:

```
expect(element.text).to eq("foo")
```

As these are rspec matchers and do not add further Capybara-style waiting specifically for the text content to become present.
Also allow artifact access to current username

Usage inside artifact is:

1. await window.discourseArtifactReady;
2. access data via window.discourseArtifactData;
AI share page assets are loaded via the app CDN, which means the requests have no authentication and will never appear to the app as "logged in". Therefore we should skip the `redirect_to_login_if_required` before_action.
This update adds a safety checker which scans the streamed updates. It ensures that incomplete segments of text are not sent yet over message bus as this will cause breakage with the diff streamer. It also updates the diff streamer to handle a thinking state for when we are waiting for message bus updates.
This change fixes two bugs and adds a safeguard.

The first issue is that the schema Gemini expected differed from the one sent, resulting in 400 errors when performing completions.

The second issue was that creating a new persona won't define a method
for `response_format`. This has to be explicitly defined when we wrap it inside the Persona class. Also, There was a mismatch between the default value and what we stored in the DB. Some parts of the code expected symbols as keys and others as strings.

Finally, we add a safeguard when, even if asked to, the model refuses to reply with a valid JSON. In this case, we are making a best-effort to recover and stream the raw response.
* FEATURE: allow researcher to also research specific topics

Also improve UI around research with more accurate info

* this ensures that under no conditions PMs will be included
* DEV: use a proper object for tool definition

This moves away from using a loose hash to define tools, which
is error prone.

Instead given a proper object we will also be able to coerce the
return values to match tool definition correctly

* fix xml tools

* fix anthropic tools

* fix specs... a few more to go

* specs are passing

* FIX: coerce values for XML tool calls

* Update spec/lib/completions/tool_definition_spec.rb

Co-authored-by: Copilot <[email protected]>

---------

Co-authored-by: Copilot <[email protected]>
This commit introduces a new Forum Researcher persona specialized in deep forum content analysis along with comprehensive improvements to our AI infrastructure.

Key additions:

    New Forum Researcher persona with advanced filtering and analysis capabilities
    Robust filtering system supporting tags, categories, dates, users, and keywords
    LLM formatter to efficiently process and chunk research results

Infrastructure improvements:

    Implemented CancelManager class to centrally manage AI completion cancellations
    Replaced callback-based cancellation with a more robust pattern
    Added systematic cancellation monitoring with callbacks

Other improvements:

    Added configurable default_enabled flag to control which personas are enabled by default
    Updated translation strings for the new researcher functionality
    Added comprehensive specs for the new components

    Renames Researcher -> Web Researcher

This change makes our AI platform more stable while adding powerful research capabilities that can analyze forum trends and surface relevant content.
Examples simulate previous interactions with an LLM and come
right after the system prompt. This helps grounding the model and
producing better responses.
This update improves the animation for streaming a diff of changes when AI helper proofread is triggered. It shows the original text with diff changes live instead of after the fact.
We were logging persona triage as "bot" in logs, causing some
confusions around real world usage

This amends it so we log usage to "automation - AUTOMATION NAME"
* DEV: Use structured responses for summaries

* Fix system specs

* Make response_format a first class citizen and update endpoints to support it

* Response format can be specified in the persona

* lint

* switch to jsonb and make column nullable

* Reify structured output chunks. Move JSON parsing to the depths of Completion

* Switch to JsonStreamingTracker for partial JSON parsing
This ensures webp / gif are converted to png prior to sending
to LLMs given webp and gif are not evenly supported.

png/jpg is universally supported and are the only supported format.

longer term we need to add support for audio/video/pdf which is supported by some models.

* more specs
This PR addresses a bug where uploads weren't being cleared after successfully posting a new private message in the AI bot conversations interface. Here's what the changes do:

## Main Fix:
- Makes the `prepareAndSubmitToBot()` method async and adds proper error handling
- Adds `this.uploads.clear()` after successful submission to clear all uploads
- Adds a test to verify that the "New Question" button properly resets the UI with no uploads

## Additional Improvements:
1. **Dynamic Character Length Validation**:
   - Uses `siteSettings.min_personal_message_post_length` instead of hardcoded 10 characters
   - Updates the error message to show the dynamic character count
   - Adds proper pluralization in the localization file for the error message

2. **Bug Fixes**:
   - Adds null checks with optional chaining (`link?.topic?.id`) in the sidebar code to prevent potential errors

3. **Code Organization**:
   - Moves error handling from the service to the controller for better separation of concerns
System personas leaned on reused classes, this was a problem
in a multisite environement cause state, such as "enabled"
ended up being reused between sites.

New implementation ensures state is pristine between sites in
a multisite

* more handling for new superclass story

* small oversight, display name should be used for display
This commit introduces file upload capabilities to the AI Bot conversations interface and improves the overall dedicated UX experience. It also changes the experimental setting to a more permanent one.

## Key changes:

- **File upload support**:
  - Integrates UppyUpload for handling file uploads in conversations
  - Adds UI for uploading, displaying, and managing attachments
  - Supports drag & drop, clipboard paste, and manual file selection
  - Shows upload progress indicators for in-progress uploads
  - Appends uploaded file markdown to message content

- **Renamed setting**:
  - Changed `ai_enable_experimental_bot_ux` to `ai_bot_enable_dedicated_ux`
  - Updated setting description to be clearer
  - Changed default value to `true` as this is now a stable feature
  - Added migration to handle the setting name change in database

- **UI improvements**:
  - Enhanced input area with better focus states
  - Improved layout and styling for conversations page
  - Added visual feedback for upload states
  - Better error handling for uploads in progress

- **Code organization**:
  - Refactored message submission logic to handle attachments
  - Updated DOM element IDs for consistency
  - Fixed focus management after submission

- **Added tests**:
  - Tests for file upload functionality
  - Tests for removing uploads before submission
  - Updated existing tests to work with the renamed setting


---------

Co-authored-by: awesomerobot <[email protected]>
Invalid access error should be populated to user when trying to search for something they do not have permissions for (i.e. anons searching `in:messages`
This commit adds an empty state when the user doesn't have any PM history. It ALSO retains the new conversation button in the sidebar so it no longer jumps. The button is disabled, icon, and text are all updated.
AI bots come in 2 flavors

1. An LLM and LLM user, in this case we should decorate posts with persona name
2. A Persona user, in this case, in PMs we decorate with LLM name

(2) is a significant improvement, cause previously when creating a conversation
you could not tell which LLM you were talking to by simply looking at the post, you would
have to scroll to the top of the page.

* lint

* translation missing
This commit enhances the AI image generation functionality by adding support for:

1. OpenAI's GPT-based image generation model (gpt-image-1)
2. Image editing capabilities through the OpenAI API
3. A new "Designer" persona specialized in image generation and editing
4. Two new AI tools: CreateImage and EditImage

Technical changes include:
- Renaming `ai_openai_dall_e_3_url` to `ai_openai_image_generation_url` with a migration
- Adding `ai_openai_image_edit_url` setting for the image edit API endpoint
- Refactoring image generation code to handle both DALL-E and the newer GPT models
- Supporting multipart/form-data for image editing requests

* wild guess but maybe quantization is breaking the test sometimes

this increases distance

* Update lib/personas/designer.rb

Co-authored-by: Alan Guo Xiang Tan <[email protected]>

* simplify and de-flake code

* fix, in chat we need enough context so we know exactly what uploads a user uploaded.

* Update lib/personas/tools/edit_image.rb

Co-authored-by: Alan Guo Xiang Tan <[email protected]>

* cleanup downloaded files right away

* fix implementation

---------

Co-authored-by: Alan Guo Xiang Tan <[email protected]>
# Preview

https://github.com/user-attachments/assets/3fe3ac8f-c938-4df4-9afe-11980046944d

# Details

- Group pms by `last_posted_at`. In this first iteration we are group by `7 days`, `30 days`, then by month beyond that.
- I inject a sidebar section link with the relative (last_posted_at) date and then update a tracked value to ensure we don't do it again. Then for each month beyond the first 30days, I add a value to the `loadedMonthLabels` set and we reference that (plus the year) to see if we need to load a new month label.
- I took the creative liberty to remove the `Conversations` section label - this had no purpose
- I hid the _collapse all sidebar sections_ carrot. This had no purpose.
- Swap `BasicTopicSerializer` to `ListableTopicSerializer` to get access to `last_posted_at`
In the last commit, I introduced a topic_custom_field to determine if a PM is indeed a bot PM.

This commit adds a migration to backfill any PM that is between 1 real user, and 1 bot. The correct topic_custom_field is added for these, so they will appear on the bot conversation sidebar properly.

We can also drop the joining to topic_users in the controller for sidebar conversations, and the isPostFromAiBot logic from the sidebar.
* FEATURE: display more places where AI is used

- Usage was not showing automation or image caption in llm list.
- Also: FIX - reasoning models would time out incorrectly after 60 seconds (raised to 10 minutes)

* correct enum not to enumerate non configured models

* FEATURE: implement chat streamer

This implements a basic chat streamer, it provides 2 things:

1. Gives feedback to the user when LLM is generating
2. Streams stuff much more efficiently to client (given it may take 100ms or so per call to update chat)
This PR is a retry of: #1135, where we migrate AiTools form to FormKit. The previous PR accidentally removed code related to setting enum values, and as a result was reverted. This update includes enums correctly along with the previous updates.
Overview
This PR introduces a Bot Homepage that was first introduced at https://ask.discourse.org/.

Key Features:
Add a bot homepage: /discourse-ai/ai-bot/conversations
Display a sidebar with previous bot conversations
Infinite scroll for large counts
Sidebar still visible when navigation mode is header_dropdown
Sidebar visible on homepage and bot PM show view
Add New Question button to the bottom of sidebar on bot PM show view
Add persona picker to homepage
This update adds metrics for estimated spending in AI usage. To make use of it, admins must add cost details to the LLM config page (input, output, and cached input costs per 1M tokens). After doing so, the metrics will appear in the AI usage dashboard as the AI plugin is used.
### 🔍 Overview
This update performs some enhancements to the LLM configuration screen. In particular, it renames the UI for the number of tokens for the prompt to "Context window" since the naming can be confusing to the user. Additionally, it adds a new optional field called "Max output tokens".
Followup fe7e73a6a4 and
1300cc8a36

Reintroduces proofreader specs and unskips ones skipped when
streaming composer suggestions were added. We just need to make sure
the jobs run immediately in specs because the job is what sends the
MessageBus event to the UI.

Also adds a pageobject method to confirm a diff is shown
in the modal before pressing Confirm button.
* FEATURE: Update model names and specs

- not a bug, but made it explicit that tools and thinking are not a chat thing
- updated all models to latest in presets (Gemini and OpenAI)

* allow larger context windows
This core PR must be merged for this to work
https://github.com/discourse/discourse/pull/32280

We want to make sure we don't have regressions with this
functionality in the rich editor, which uses contendeditable
and other APIs than the old composer.
1. Add age of post to topic context (1 month ago, 1 year ago, etc)
2. Refactor code for simplicity
3. Fix handling of post context in DMs which was not using new handling of uploads
Previous to this fix we assumed the name field contained usernames
when in fact it was stored in the id field.

This fixes the context contruction and also adds some basic user
information to the context to assist responders in understanding
the cast of chars
In this feature update, we add the UI for the ability to easily configure persona backed AI-features. The feature will still be hidden until structured responses are complete.
This update fixes a few issues in the split topic suggester. It fixes an issue where not all the category suggestions were appearing in the client. It also fixes an issue where the `move-post` request fails when creating a new topic with only one tag suggestion.
Add API methods to AI tools for reading and updating personas, enabling
more flexible AI workflows. This allows custom tools to:

- Fetch persona information through discourse.getPersona()
- Update personas with modified settings via discourse.updatePersona()
- Also update using persona.update()

These APIs enable new use cases like "trainable" moderation bots, where
users with appropriate permissions can set and refine moderation rules
through direct chat interactions, without needing admin panel access.

Also adds a special API scope which allows people to lean on API
for similar actions

Additionally adds a rather powerful hidden feature can allow custom tools
to inject content into the context unconditionally it can be used for memory and similar features
This update fixes a few small quirks with Discobot discoveries:
- [X] subsequent searches should work correctly
- [X] discovery timeout should maintain UI
- [X] key up/down traversal of regular search results should still work
Previously, allowing "everyone" to access gists meant anons would see them too.
With the move to Personas, we used "[]" to reflect that.

With discourse/discourse#32199 adding the "everyone" option to the personas-allowed
groups, we are switching back to the original behavior.
Leaving allowed groups empty should always mean nobody can use the feature.
We started used a callback as a buffer in FoldContent, so the Fake endpoint is attempting
to emulate delays in the streaming. However, we don't care about that in these specs.
* REFACTOR: Move personas into it's own module.

* WIP: Use personas for summarization

* Prioritize persona default LLM or fallback to newest one

* Simplify summarization strategy

* Keep ai_sumarization_model as a fallback
This feature update allows for continuing the conversation with Discobot Discoveries in an AI bot chat. After discoveries gives you a response to your search you can continue with the existing context.
This change moves all the personas code into its own module. We want to treat them as a building block features can built on top of, same as `Completions::Llm`.

The code to title a message was moved from `Bot` to `Playground`.
* DEV: refactor bot internals

This introduces a proper object for bot context, this makes
it simpler to improve context management as we go cause we
have a nice object to work with

Starts refactoring allowing for a single message to have
multiple uploads throughout

* transplant method to message builder

* chipping away at inline uploads

* image support is improved but not fully fixed yet

partially working in anthropic, still got quite a few dialects to go

* open ai and claude are now working

* Gemini is now working as well

* fix nova

* more dialects...

* fix ollama

* fix specs

* update artifact fixed

* more tests

* spam scanner

* pass more specs

* bunch of specs improved

* more bug fixes.

* all the rest of the tests are working

* improve tests coverage and ensure custom tools are aware of new context object

* tests are working, but we need more tests

* resolve merge conflict

* new preamble and expanded specs on ai tool

* remove concept of "standalone tools"

This is no longer needed, we can set custom raw, tool details are injected into tool calls
**This update makes a few improvements to search discoveries:**
- [x] in search menu panel: search discoveries should still be triggered when no regular results are present
- [x] in full page search: search discoveries should still be triggered when no regular results are present
- [x] flakiness in search discoveries sometimes not working properly.

---------

Co-authored-by: awesomerobot <[email protected]>
* wip: more dynamic availableForcedTools

* FIX: forced tools wasn't set correctly when tool has no options.

---------

Co-authored-by: Roman Rizzi <[email protected]>
The AI Tool spec that checks that the tool runner will not timeout on slow HTTP request is flaky. In this PR we attempt to resolve the flakiness by:

Ensuring stub_request runs before the request
Increasing the timeout for CI env
This takes the logic used in summarization/discoveries for streaming and consolidates it into a single helper lib for smooth streaming. It introduces a new lib: `SmoothStreamer` that can be used by components for smooth streaming text from message bus updates. Additionally, the PR makes use of that new lib in the AI post menu helper.
The older design approach for sentiment analysis report needed the click outside logic. However, when the design was changed this logic was accidentally left behind. It is potentially causing some negative performance impacts. This PR removes the old unnecessary logic.
This PR ensures that the category badges are present in the sentiment analysis report. Since the core change in https://github.com/discourse/discourse/pull/31795, there was a regression in the post list drill-down where category badges were not being shown. This PR fixes that and also ensures icons/emojis are shown when categories make use of them. This PR also adds the category badge in the table list.
This update fixes an issue where the results of the post helper menu was not selectable. Previously, selecting any text inside the menu was immediately closing the menu.
The sentiment analysis report page initially showcases sentiments via category/tag by doughnut visualizations. However, this isn't an optimal view for quickly scanning and comparing each result. This PR updates the overview to include a table visualization with horizontal bars to represent sentiment analysis instead of doughnuts. Doughnut visualizations are still maintained however when accessing the sentiment data in the drill down for individual entries.

This approach is an intermediary step, as we will eventually add whole clustering and sizing visualization instead of a table. As such, no relevant tests are added in this PR.
This PR adds support for disabling further tool calls by setting tool_choice to :none across all supported LLM providers:

- OpenAI: Uses "none" tool_choice parameter
- Anthropic: Uses {type: "none"} and adds a prefill message to prevent confusion
- Gemini: Sets function_calling_config mode to "NONE"
- AWS Bedrock: Doesn't natively support tool disabling, so adds a prefill message

We previously used to disable tool calls by simply removing tool definitions, but this would cause errors with some providers. This implementation uses the supported method appropriate for each provider while providing a fallback for Bedrock.

Co-authored-by: Natalie Tay <[email protected]>

* remove stray puts

* cleaner chain breaker for last tool call (works in thinking)

remove unused code

* improve test

---------

Co-authored-by: Natalie Tay <[email protected]>
This PR fixes an issue where you are unable to click to see the sentiment drill-down when there are no current filters applied. This is due to trying to `JSON.parse()` the filters when there are no filters. This fix ensures there are filters first before trying to parse the JSON.
* REFACTOR: Migrate Personas' form to FormKit

We re-arranged fields into sections so we can better differentiate which options are specific to the AI bot.

* few form-kit improvements

https://github.com/discourse/discourse/pull/31934

---------

Co-authored-by: Joffrey JAFFEUX <[email protected]>
form.Object and form.Collection have been changed. Most importantly formObject doesnt yield name but data. It's not your responsibility to build an array of fields.
This allows for a new mode in persona triage where nothing is posted on topics.

This allows people to perform all triage actions using tools

Additionally introduces new APIs to create chat messages from tools which can be useful in certain moderation scenarios

Co-authored-by: Natalie Tay <[email protected]>

* remove TODO code

---------

Co-authored-by: Natalie Tay <[email protected]>
When editing a topic (instead of creating one) and using the
tag/category suggestion buttons. We want to use existing topic
embeddings instead of creating new ones.
- Fix search API to only include column_names when present to make the API less confusing
- Ensure correct LLM is used in PMs by tracking and preferring the last bot user
- Fix persona_id conversion from string to integer in custom fields
- Add missing test for PM triage with no replies - ensure we don't try to auto title topic
- Ensure bot users are properly added to PMs
- Make title setting optional when replying to posts
- Add ability to control stream_reply behavior

These changes improve reliability and fix edge cases in bot interactions,
particularly in private messages with multiple LLMs and while triaging posts using personas
thinking models such as Claude 3.7 Thinking and o1 / o3 do not
support top_p or temp.

Previously you would have to carefully remove it from everywhere
by having it be a provider param we now support blanker removing
without forcing people to update automation rules or personas
When spam scanner is enabled and code is reloaded, developer experience this error:

```
NameError at /posts
===================

uninitialized constant DiscourseAi::AiModeration::EntryPoint::SpamScanner

> To access an interactive console with this error, point your browser to: /__better_errors

plugins/discourse-ai/lib/ai_moderation/entry_point.rb, line 7
```

It is because when we call `SpamScanner` it is searched within parent `DiscourseAi::AiModeration::EntryPoint` namespace.

We can help a bit Zeitwerk by calling SpamScanner more explicitly.
This update adds the ability to disable search discoveries. This can be done through a tooltip when search discoveries are shown. It can also be done in the AI user preferences, which has also been updated to accommodate more than just the one image caption setting.
### ✨ What's new?
- [X] show sentiment counts by color on doughnut without needing to hover
- [X] minor UI padding adjustments
- [X] hide filters that are not allowed to be adjusted in selected chart view
- [X] fix z-index issues with drill-down filters
Adds a new rake task to generate topics using the AI helper model.
Generate topics using
```
bundle exec rake "ai:generate_topics[Don Quijote de la Mancha\, Cien años de soledad\, Os Lusíadas\,三国演义]"
```
For now it randomly chooses a non-read-restricted category and a random bunch of users.
This PR enhances the LLM triage automation with several important improvements:
- Add ability to use AI personas for automated replies instead of canned replies
- Add support for whisper responses
- Refactor LLM persona reply functionality into a reusable method
- Add new settings to configure response behavior in automations
- Improve error handling and logging
- Fix handling of personal messages in the triage flow
- Add comprehensive test coverage for new features
- Make personas configurable with more flexible requirements
This allows for more dynamic and context-aware responses in automated workflows, with better control over visibility and attribution.
## LLM Persona Triage
- Allows automated responses to posts using AI personas
- Configurable to respond as regular posts or whispers
- Adds context-aware formatting for topics and private messages
- Provides special handling for topic metadata (title, category, tags)
## LLM Tool Triage
- Enables custom AI tools to process and respond to posts
- Tools can analyze post content and invoke personas when needed
- Zero-parameter tools can be used for automated workflows
- Not enabled in production yet
## Implementation Details
- Added new scriptable registration in discourse_automation/ directory
- Created core implementation in lib/automation/ modules
- Enhanced PromptMessagesBuilder with topic-style formatting
- Added helper methods for persona and tool selection in UI
- Extended AI Bot functionality to support whisper responses
- Added rate limiting to prevent abuse
## Other Changes
- Added comprehensive test coverage for both automation types
- Enhanced tool runner with LLM integration capabilities
- Improved error handling and logging
This feature allows forum admins to configure AI personas to automatically respond to posts based on custom criteria and leverage AI tools for more complex triage workflows.
Tool Triage has been disabled in production while we finalize details of new scripting capabilities.
**This PR includes a variety of updates to the Sentiment Analysis report:**
- [X] Conditionally showing sentiment reports based on `sentiment_enabled` setting
- [X] Sentiment reports should only be visible in sidebar if data is in the reports
- [X] Fix infinite loading of posts in drill down
- [x] Fix markdown emojis showing not showing as emoji representation
- [x] Drill down of posts should have URL
- [x] ~~Different doughnut sizing based on post count~~ [reverting and will address in follow-up (see: `/t/146786/47`)]
- [X] Hide non-functional export button
- [X] Sticky drill down filter nav
adds support for "thinking tokens" - a feature that exposes the model's reasoning process before providing the final response. Key improvements include:
- Add a new Thinking class to handle thinking content from LLMs
- Modify endpoints (Claude, AWS Bedrock) to handle thinking output
- Update AI bot to display thinking in collapsible details section
- Fix SEARCH/REPLACE blocks to support empty replacement strings and general improvements to artifact editing
- Allow configurable temperature in triage and report automations
- Various bug fixes and improvements to diff parsing
## 🔍 Overview
This update ensures that the streaming for discoveries is smoother, especially on first update.
## ➕ More details
To help with smoother streaming, the discovery preview (which was being tracked as a separate property in the JS logic) will be removed and the entire discovery content will be shown/hidden via the existing CSS. The preview was already receiving the full update even though it was visually hidden, so removing the separate property shouldn't have any negative performance hit. Visually hiding it with CSS only will help simplify the component and also allow for smoother streaming. We will instead remove the buffered streaming approach and instead use typing timers similar to what we did for streaming summarization.
No related tests as streaming animations are difficult to test.
This update improves some of the UI around sentiment analysis reports:
1. Improve titles so it is above and truncated when long
2. Change doughnut to only show total count
3. Ensures sentiment posts have dates
4. Ensure expand post doesn't appear on short posts
* FEATURE: full support for Sonnet 3.7
- Adds support for Sonnet 3.7 with reasoning on bedrock and anthropic
- Fixes regression where provider params were not populated
Note. reasoning tokens are hardcoded to minimum of 100 maximum of 65536
* FIX: open ai non reasoning models need to use deprecate max_tokens
* FIX: legacy reasoning models not working, missing provider params
1. Legacy reasoning models (o1-preview / o1-mini) do not support developer or system messages, do not use them.
2. LLM editor form not showing all provider params due to missing remap
* add system test
* FEATURE: Experimental search results from an AI Persona.
When a user searches discourse, we'll send the query to an AI Persona to provide additional context and enrich the results. The feature depends on the user being a member of a group to which the persona has access.
* Update assets/stylesheets/common/ai-blinking-animation.scss
Co-authored-by: Keegan George <[email protected]>
---------

Co-authored-by: Keegan George <[email protected]>
## 🔍 Overview
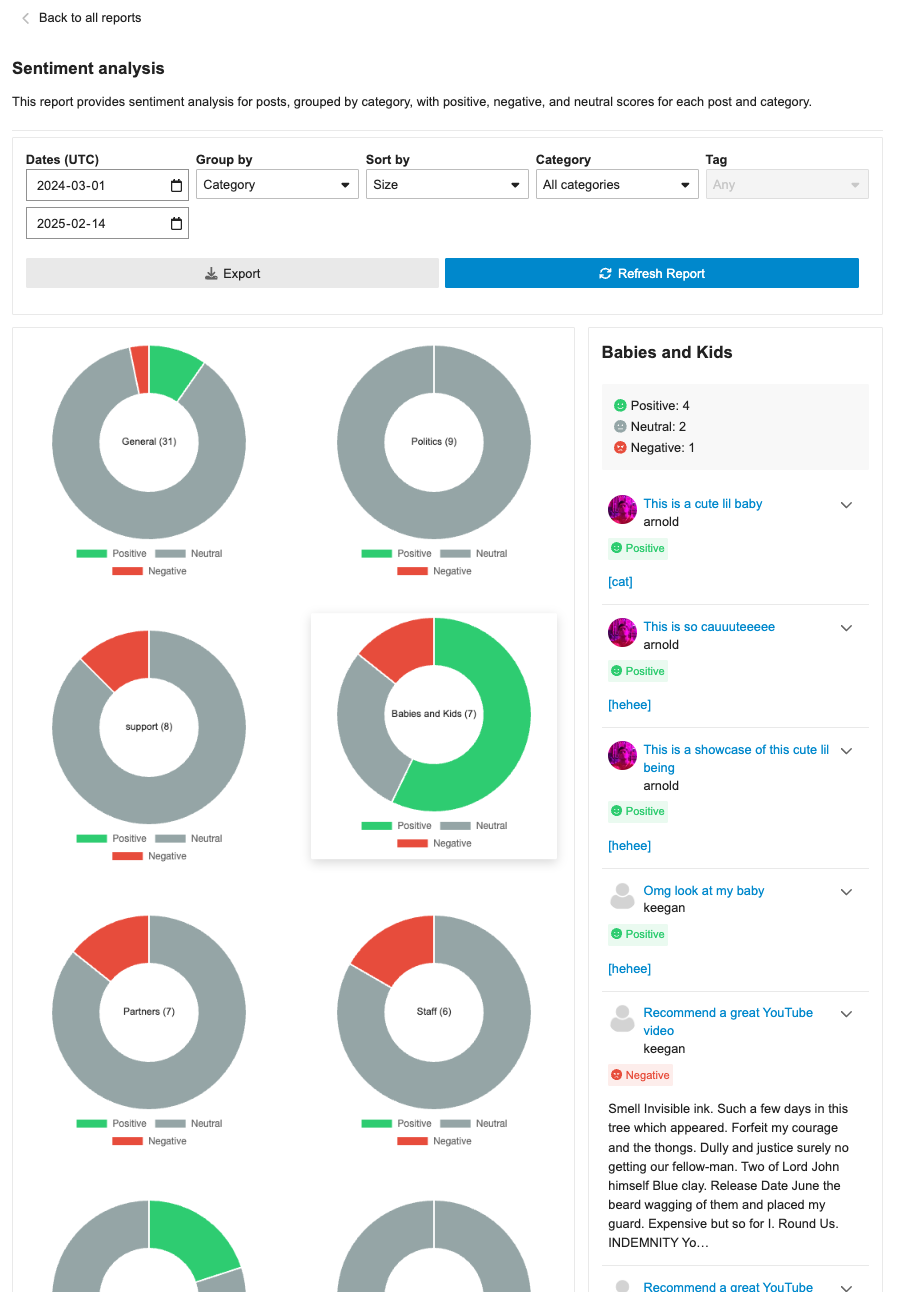
This update adds a new report page at `admin/reports/sentiment_analysis` where admins can see a sentiment analysis report for the forum grouped by either category or tags.
## ➕ More details
The report can breakdown either category or tags into positive/negative/neutral sentiments based on the grouping (category/tag). Clicking on the doughnut visualization will bring up a post list of all the posts that were involved in that classification with further sentiment classifications by post.
The report can additionally be sorted in alphabetical order or by size, as well as be filtered by either category/tag based on the grouping.
## 👨🏽💻 Technical Details
The new admin report is registered via the pluginAPi with `api.registerReportModeComponent` to register the custom sentiment doughnut report. However, when each doughnut visualization is clicked, a new endpoint found at: `/discourse-ai/sentiment/posts` is fetched to showcase posts classified by sentiments based on the respective params.
## 📸 Screenshots
The require for `discourse/config/environment` should point to the local user's core Discourse environment instead of the hardcoded path for Sam's env.
From [pgvector/pgvector](https://github.com/pgvector/pgvector) README

> With approximate indexes, filtering is applied after the index is scanned. If a condition matches 10% of rows, with HNSW and the default hnsw.ef_search of 40, only 4 rows will match on average. For more rows, increase hnsw.ef_search.
>
> Starting with 0.8.0, you can enable [iterative index scans](https://github.com/pgvector/pgvector#iterative-index-scans), which will automatically scan more of the index when needed.


Since we are stuck on 0.7.0 we are going the first option for now.
- Add non-contiguous search/replace support using ... syntax
- Add judge support for evaluating LLM outputs with ratings
- Improve error handling and reporting in eval runner
- Add full section replacement support without search blocks
- Add fabricators and specs for artifact diffing
- Track failed searches to improve debugging
- Add JS syntax validation for artifact versions in eval system
- Update prompt documentation with clear guidelines

* improve eval output

* move error handling

* llm as a judge

* fix spec

* small note on evals
* FEATURE: Native PDF support

This amends it so we use PDF Reader gem to extract text from PDFs

* This means that our simple pdf eval passes at last

* fix spec

* skip test in CI

* test file support

* Update lib/utils/image_to_text.rb

Co-authored-by: Alan Guo Xiang Tan <[email protected]>

* address pr comments

---------

Co-authored-by: Alan Guo Xiang Tan <[email protected]>
This PR introduces several enhancements and refactorings to the AI Persona and RAG (Retrieval-Augmented Generation) functionalities within the discourse-ai plugin. Here's a breakdown of the changes:

**1. LLM Model Association for RAG and Personas:**

-   **New Database Columns:** Adds `rag_llm_model_id` to both `ai_personas` and `ai_tools` tables. This allows specifying a dedicated LLM for RAG indexing, separate from the persona's primary LLM.  Adds `default_llm_id` and `question_consolidator_llm_id` to `ai_personas`.
-   **Migration:**  Includes a migration (`20250210032345_migrate_persona_to_llm_model_id.rb`) to populate the new `default_llm_id` and `question_consolidator_llm_id` columns in `ai_personas` based on the existing `default_llm` and `question_consolidator_llm` string columns, and a post migration to remove the latter.
-   **Model Changes:**  The `AiPersona` and `AiTool` models now `belong_to` an `LlmModel` via `rag_llm_model_id`. The `LlmModel.proxy` method now accepts an `LlmModel` instance instead of just an identifier.  `AiPersona` now has `default_llm_id` and `question_consolidator_llm_id` attributes.
-   **UI Updates:**  The AI Persona and AI Tool editors in the admin panel now allow selecting an LLM for RAG indexing (if PDF/image support is enabled).  The RAG options component displays an LLM selector.
-   **Serialization:** The serializers (`AiCustomToolSerializer`, `AiCustomToolListSerializer`, `LocalizedAiPersonaSerializer`) have been updated to include the new `rag_llm_model_id`, `default_llm_id` and `question_consolidator_llm_id` attributes.

**2. PDF and Image Support for RAG:**

-   **Site Setting:** Introduces a new hidden site setting, `ai_rag_pdf_images_enabled`, to control whether PDF and image files can be indexed for RAG. This defaults to `false`.
-   **File Upload Validation:** The `RagDocumentFragmentsController` now checks the `ai_rag_pdf_images_enabled` setting and allows PDF, PNG, JPG, and JPEG files if enabled.  Error handling is included for cases where PDF/image indexing is attempted with the setting disabled.
-   **PDF Processing:** Adds a new utility class, `DiscourseAi::Utils::PdfToImages`, which uses ImageMagick (`magick`) to convert PDF pages into individual PNG images. A maximum PDF size and conversion timeout are enforced.
-   **Image Processing:** A new utility class, `DiscourseAi::Utils::ImageToText`, is included to handle OCR for the images and PDFs.
-   **RAG Digestion Job:** The `DigestRagUpload` job now handles PDF and image uploads. It uses `PdfToImages` and `ImageToText` to extract text and create document fragments.
-   **UI Updates:**  The RAG uploader component now accepts PDF and image file types if `ai_rag_pdf_images_enabled` is true. The UI text is adjusted to indicate supported file types.

**3. Refactoring and Improvements:**

-   **LLM Enumeration:** The `DiscourseAi::Configuration::LlmEnumerator` now provides a `values_for_serialization` method, which returns a simplified array of LLM data (id, name, vision_enabled) suitable for use in serializers. This avoids exposing unnecessary details to the frontend.
-   **AI Helper:** The `AiHelper::Assistant` now takes optional `helper_llm` and `image_caption_llm` parameters in its constructor, allowing for greater flexibility.
-   **Bot and Persona Updates:** Several updates were made across the codebase, changing the string based association to a LLM to the new model based.
-   **Audit Logs:** The `DiscourseAi::Completions::Endpoints::Base` now formats raw request payloads as pretty JSON for easier auditing.
- **Eval Script:** An evaluation script is included.

**4. Testing:**

-    The PR introduces a new eval system for LLMs, this allows us to test how functionality works across various LLM providers. This lives in `/evals`
Prior to this commit, editing the provider wouldn't recompute the provider params. It would also not correctly recompute the "canEditURL" property.

To make possible this commit has:
- made a fix in core: https://github.com/discourse/discourse/pull/31329
- ensures the provider params are recomputed when provider is changed
- made the check on `canEditURL` based on form state and not initial model value

Tests have been added to confirm the expected behavior.
When you already have embeddings for a model stored and change models,
our backfill script was failing to backfill the newly configured model.

Regression introduced most likely in 1686a8a
Currently in core re-flagging something that is already flagged as spam
is not supported, long term we may want to support this but in the meantime
we should not be silencing/hiding if the PostActionCreator fails
when flagging things as spam.

---------

Co-authored-by: Ted Johansson <[email protected]>
* FEATURE: Tool name validation

- Add unique index to the name column of the ai_tools table
- correct our tests for AiToolController
- tool_name field which will be used to represent to LLM
- Add tool_name to Tools's presets
- Add duplicate tools validation for AiPersona
- Add unique constraint to the name column of the ai_tools table

* DEV: Validate duplicate tool_name between builin tools and custom tools

* lint

* chore: fix linting

* fix conlict mistakes

* chore: correct icon class

* chore: fix failed specs

* Add max_length to tool_name

* chore: correct the option name

* lintings

* fix lintings
Before this change, a summary was only outdated when new content appeared, for topics with "best replies", when the query returned different results. The intent behind this change is to detect when a summary is outdated as a result of an edit.

Additionally, we are changing the backfill candidates query to compare "ai_summary_backfill_topic_max_age_days" against "last_posted_at" instead of "created_at", to catch long-lived, active topics. This was discussed here: https://meta.discourse.org/t/ai-summarization-backfill-is-stuck-keeps-regenerating-the-same-topic/347088/14?u=roman_rizzi
### Why

This pull request fundamentally restructures how AI bots create and update web artifacts to address critical limitations in the previous approach:

1.  **Improved Artifact Context for LLMs**: Previously, artifact creation and update tools included the *entire* artifact source code directly in the tool arguments. This overloaded the Language Model (LLM) with raw code, making it difficult for the LLM to maintain a clear understanding of the artifact's current state when applying changes. The LLM would struggle to differentiate between the base artifact and the requested modifications, leading to confusion and less effective updates.
2.  **Reduced Token Usage and History Bloat**: Including the full artifact source code in every tool interaction was extremely token-inefficient.  As conversations progressed, this redundant code in the history consumed a significant number of tokens unnecessarily. This not only increased costs but also diluted the context for the LLM with less relevant historical information.
3.  **Enabling Updates for Large Artifacts**: The lack of a practical diff or targeted update mechanism made it nearly impossible to efficiently update larger web artifacts.  Sending the entire source code for every minor change was both computationally expensive and prone to errors, effectively blocking the use of AI bots for meaningful modifications of complex artifacts.

**This pull request addresses these core issues by**:

*   Introducing methods for the AI bot to explicitly *read* and understand the current state of an artifact.
*   Implementing efficient update strategies that send *targeted* changes rather than the entire artifact source code.
*   Providing options to control the level of artifact context included in LLM prompts, optimizing token usage.

### What

The main changes implemented in this PR to resolve the above issues are:

1.  **`Read Artifact` Tool for Contextual Awareness**:
    - A new `read_artifact` tool is introduced, enabling AI bots to fetch and process the current content of a web artifact from a given URL (local or external).
    - This provides the LLM with a clear and up-to-date representation of the artifact's HTML, CSS, and JavaScript, improving its understanding of the base to be modified.
    - By cloning local artifacts, it allows the bot to work with a fresh copy, further enhancing context and control.

2.  **Refactored `Update Artifact` Tool with Efficient Strategies**:
    - The `update_artifact` tool is redesigned to employ more efficient update strategies, minimizing token usage and improving update precision:
        - **`diff` strategy**:  Utilizes a search-and-replace diff algorithm to apply only the necessary, targeted changes to the artifact's code. This significantly reduces the amount of code sent to the LLM and focuses its attention on the specific modifications.
        - **`full` strategy**:  Provides the option to replace the entire content sections (HTML, CSS, JavaScript) when a complete rewrite is required.
    - Tool options enhance the control over the update process:
        - `editor_llm`:  Allows selection of a specific LLM for artifact updates, potentially optimizing for code editing tasks.
        - `update_algorithm`: Enables choosing between `diff` and `full` update strategies based on the nature of the required changes.
        - `do_not_echo_artifact`:  Defaults to true, and by *not* echoing the artifact in prompts, it further reduces token consumption in scenarios where the LLM might not need the full artifact context for every update step (though effectiveness might be slightly reduced in certain update scenarios).

3.  **System and General Persona Tool Option Visibility and Customization**:
    - Tool options, including those for system personas, are made visible and editable in the admin UI. This allows administrators to fine-tune the behavior of all personas and their tools, including setting specific LLMs or update algorithms. This was previously limited or hidden for system personas.

4.  **Centralized and Improved Content Security Policy (CSP) Management**:
    - The CSP for AI artifacts is consolidated and made more maintainable through the `ALLOWED_CDN_SOURCES` constant. This improves code organization and future updates to the allowed CDN list, while maintaining the existing security posture.

5.  **Codebase Improvements**:
    - Refactoring of diff utilities, introduction of strategy classes, enhanced error handling, new locales, and comprehensive testing all contribute to a more robust, efficient, and maintainable artifact management system.

By addressing the issues of LLM context confusion, token inefficiency, and the limitations of updating large artifacts, this pull request significantly improves the practicality and effectiveness of AI bots in managing web artifacts within Discourse.
* DEV: raise timeout for reasoning LLMs

* FIX: use id to identify llms, not model_name

model_name is not unique, in the case of reasoning models
you may configure the same llm multiple times using different
reasoning levels.
This update resolves a regression that was introduced in https://github.com/discourse/discourse-ai/pull/1036/files. Previously, only seeded models that were allowed could be configured for model settings. However, in our attempts to prevent unreachable LLM errors from not allowing settings to persist, it also unknowingly allowed seeded models that were not allowed to be configured. This update resolves this issue, while maintaining the ability to still set unreachable LLMs.
Before this change, we let you set the embeddings selected model back to " " even with embeddings enabled. This will leave the site in a broken state.

Additionally, it adds a fail-safe for these scenarios to avoid errors on the topics page.
We have removed this flag in core. All plugins now use the "top mode" for their navigation. A backwards-compatible change has been made in core while we remove the usage from plugins.
This change fixes two different problems.

First, we add a data migration to migrate the configuration of sites using Open AI's embedding model. There was a window between the embedding config changes and #1087, where sites could end up in a broken state due to an unconfigured selected model setting, as reported on https://meta.discourse.org/t/-/348964

The second fix drops pre-seeded search indexes of the models we didn't migrate and corrects the ones where the dimensions don't match. Since the index uses the model ID, new embedding configs could use one of these ones even when the dimensions no longer match.
This should give us a better idea on how our scanner is faring across sites.

```
# HELP discourse_discourse_ai_spam_detection AI spam scanning statistics
# TYPE discourse_discourse_ai_spam_detection counter
discourse_discourse_ai_spam_detection{db="default",type="scanned"} 16
discourse_discourse_ai_spam_detection{db="default",type="is_spam"} 7
discourse_discourse_ai_spam_detection{db="default",type="false_positive"} 1
discourse_discourse_ai_spam_detection{db="default",type="false_negative"} 2
```
We have a flag to signal we are shortening the embeddings of a model.
Only used in Open AI's text-embedding-3-*, but we plan to use it for other services.
* Use AR model for embeddings features

* endpoints

* Embeddings CRUD UI

* Add presets. Hide a couple more settings

* system specs

* Seed embedding definition from old settings

* Generate search bit index on the fly. cleanup orphaned data

* support for seeded models

* Fix run test for new embedding

* fix selected model not set correctly
This adds registration and last known IP information and email to scanning context.

This provides another hint for spam scanner about possible malicious users.

For example registered in India, replying from Australia or
email is clearly a throwaway email address.
To quickly select backfill candidates without comparing SHAs, we compare the last summarized post to the topic's highest_post_number. However, hiding or deleting a post and adding a small action will update this column, causing the job to stall and re-generate the same summary repeatedly until someone posts a regular reply. On top of this, this is not always true for topics with `best_replies`, as this last reply isn't necessarily included.

Since this is not evident at first glance and each summarization strategy picks its targets differently, I'm opting to simplify the backfill logic and how we track potential candidates.

The first step is dropping `content_range`, which serves no purpose and it's there because summary caching was supposed to work differently at the beginning. So instead, I'm replacing it with a column called `highest_target_number`, which tracks `highest_post_number` for topics and could track other things like channel's `message_count` in the future.

Now that we have this column when selecting every potential backfill candidate, we'll check if the summary is truly outdated by comparing the SHAs, and if it's not, we just update the column and move on
When enabling spam scanner it there may be old unscanned posts
this can create a risky situation where spam scanner operates
on legit posts during false positives

To keep this a lot safer we no longer try to hide old stuff by
the spammers.
This update fixes an issue when the composer helper menu was not being shown on tablets in desktop mode. Updating the `z-index` to use the modal-dialog case is more appropriate here.
Adds a comprehensive quota management system for LLM models that allows:

- Setting per-group (applied per user in the group) token and usage limits with configurable durations
- Tracking and enforcing token/usage limits across user groups
- Quota reset periods (hourly, daily, weekly, or custom)
-  Admin UI for managing quotas with real-time updates

This system provides granular control over LLM API usage by allowing admins
to define limits on both total tokens and number of requests per group.
Supports multiple concurrent quotas per model and automatically handles
quota resets.


Co-authored-by: Keegan George <[email protected]>
Disabling streaming is required for models such o1 that do not have streaming
enabled yet

It is good to carry this feature around in case various apis decide not to support streaming endpoints and Discourse AI can continue to work just as it did before.

Also: fixes issue where sharing artifacts would miss viewport leading to tiny artifacts on mobile
This update adds some structure for handling errors in the spam config while also handling a specific error related to the spam scanning user not being an admin account.
The seeded LLM setting: `SiteSetting.ai_spam_detection_model_allowed_seeded_models` returns a _string_ with IDs separated by pipes. running `_map` on it will return an array with strings. We were previously checking for the id with custom prefix identifier, but instead we should be checking the stringified ID.
* FEATURE: smart date support for AI helper

This feature allows conversion of human typed in dates and times
to smart "Discourse" timezone friendly dates.

* fix specs and lint

* lint

* address feedback

* add specs
This PR fixes an issue where LLM enumerator would error out when `SiteSetting.ai_spam_detection = true` but there was no `AiModerationSetting.spam` present.

Typically, we add an `LlmDependencyValidator` for the setting itself, however, since Spam is unique in that it has it's model set in `AiModerationSetting` instead of a `SiteSetting`, we'll add a simple check here to prevent erroring out.
Previously we had the behaviour for model settings so that when you try and set a model, it runs a test and returns an error if it can't run the test successfully. The error then prevents you from setting the site setting.

This results in some issues when we try and automate things. This PR updates that so that the test runs and discreetly logs the changes, but doesn't prevent the setting from being set. Instead we rely on "run test" in the LLM config along with ProblemChecks to catch issues.
Previous version was prone to the bug:

https://github.com/ruby-concurrency/concurrent-ruby/issues/1075

This is particularly bad cause we could have a DB connection
attached to the thread and we never clear it up, so after N hours
this could start exhibiting weird connection issues.
Some files were not shown because too many files have changed in this diff
Show More
Reference in New Issue
Block a user
Blocking a user prevents them from interacting with repositories, such as opening or commenting on pull requests or issues. Learn more about blocking a user.
 Sam
 Jarek Radosz
 Alan Guo Xiang Tan
 Natalie Tay
 Roman Rizzi
 Kris
 Discourse Translator Bot
 Martin Brennan
 Keegan George
 Rafael dos Santos Silva
 Joffrey JAFFEUX
 moin-Jana
 Yuriy Kurant

 dependabot[bot]
 Mark VanLandingham
 Guhyoun Nam
 David Taylor
 Jordan Vidrine

 Isaac Janzen

 Sérgio Saquetim
 Renato Atilio
 Loïc Guitaut
 Régis Hanol
 Penar Musaraj
 Kelv
 Ted Johansson
 David Battersby
 Hoa Nguyen
 我秦始皇